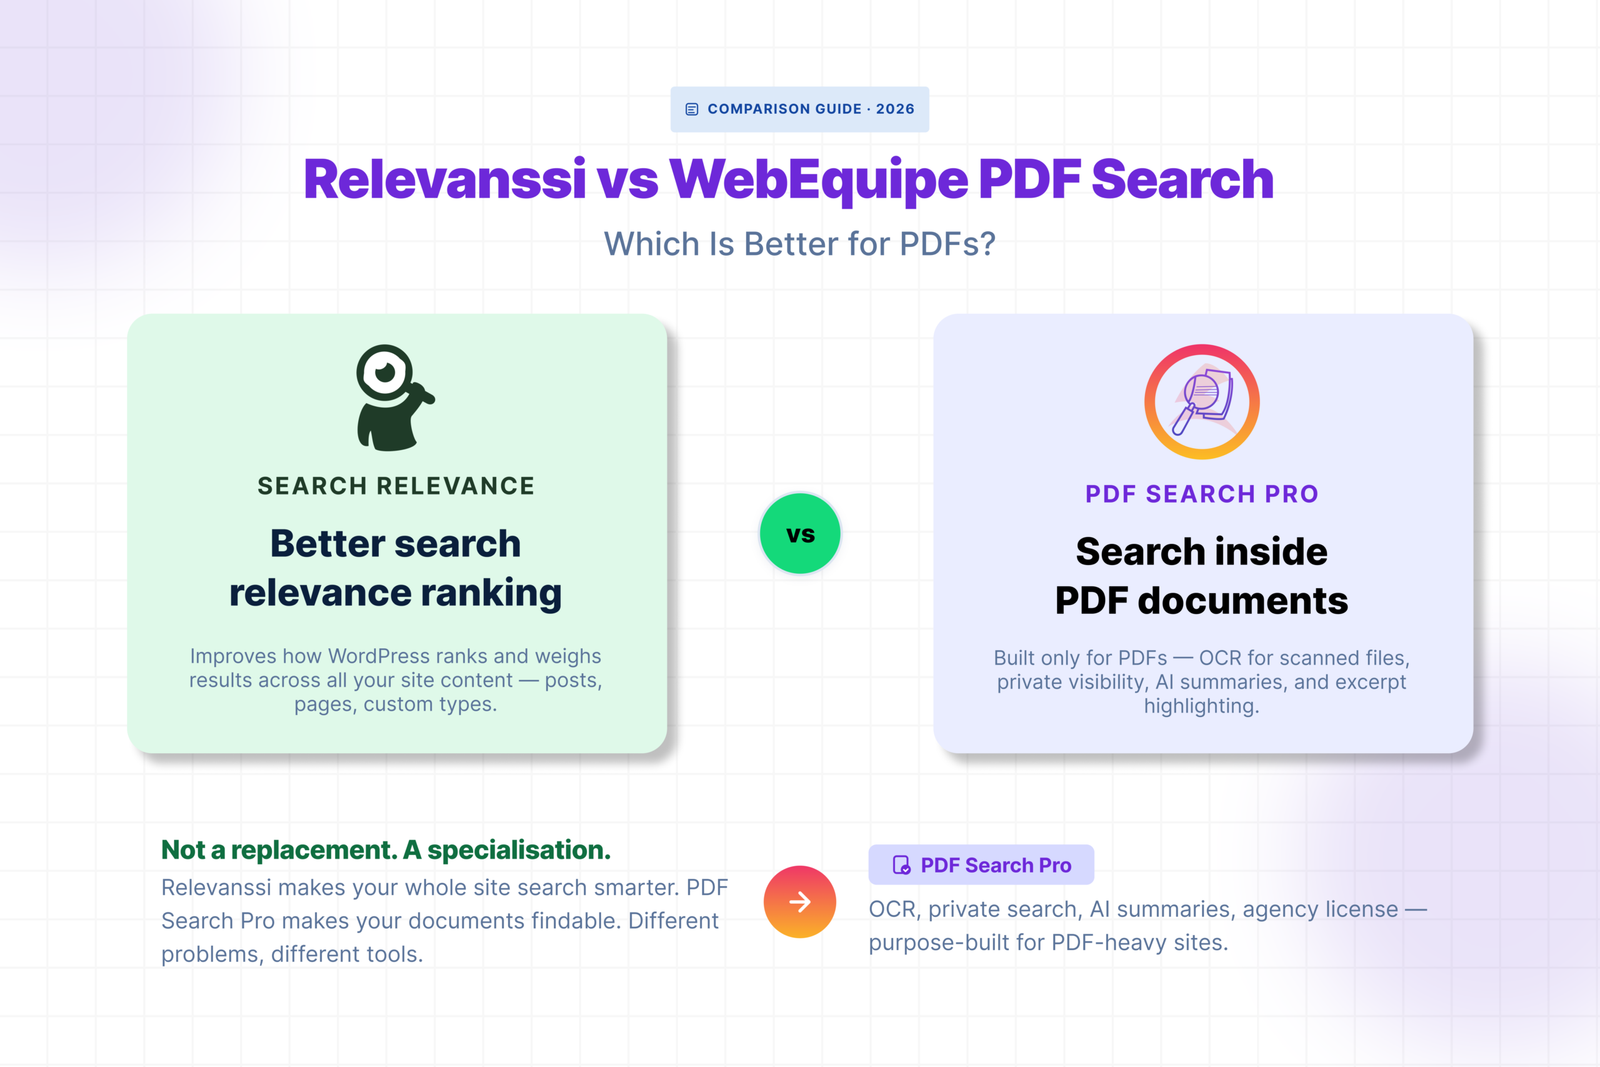
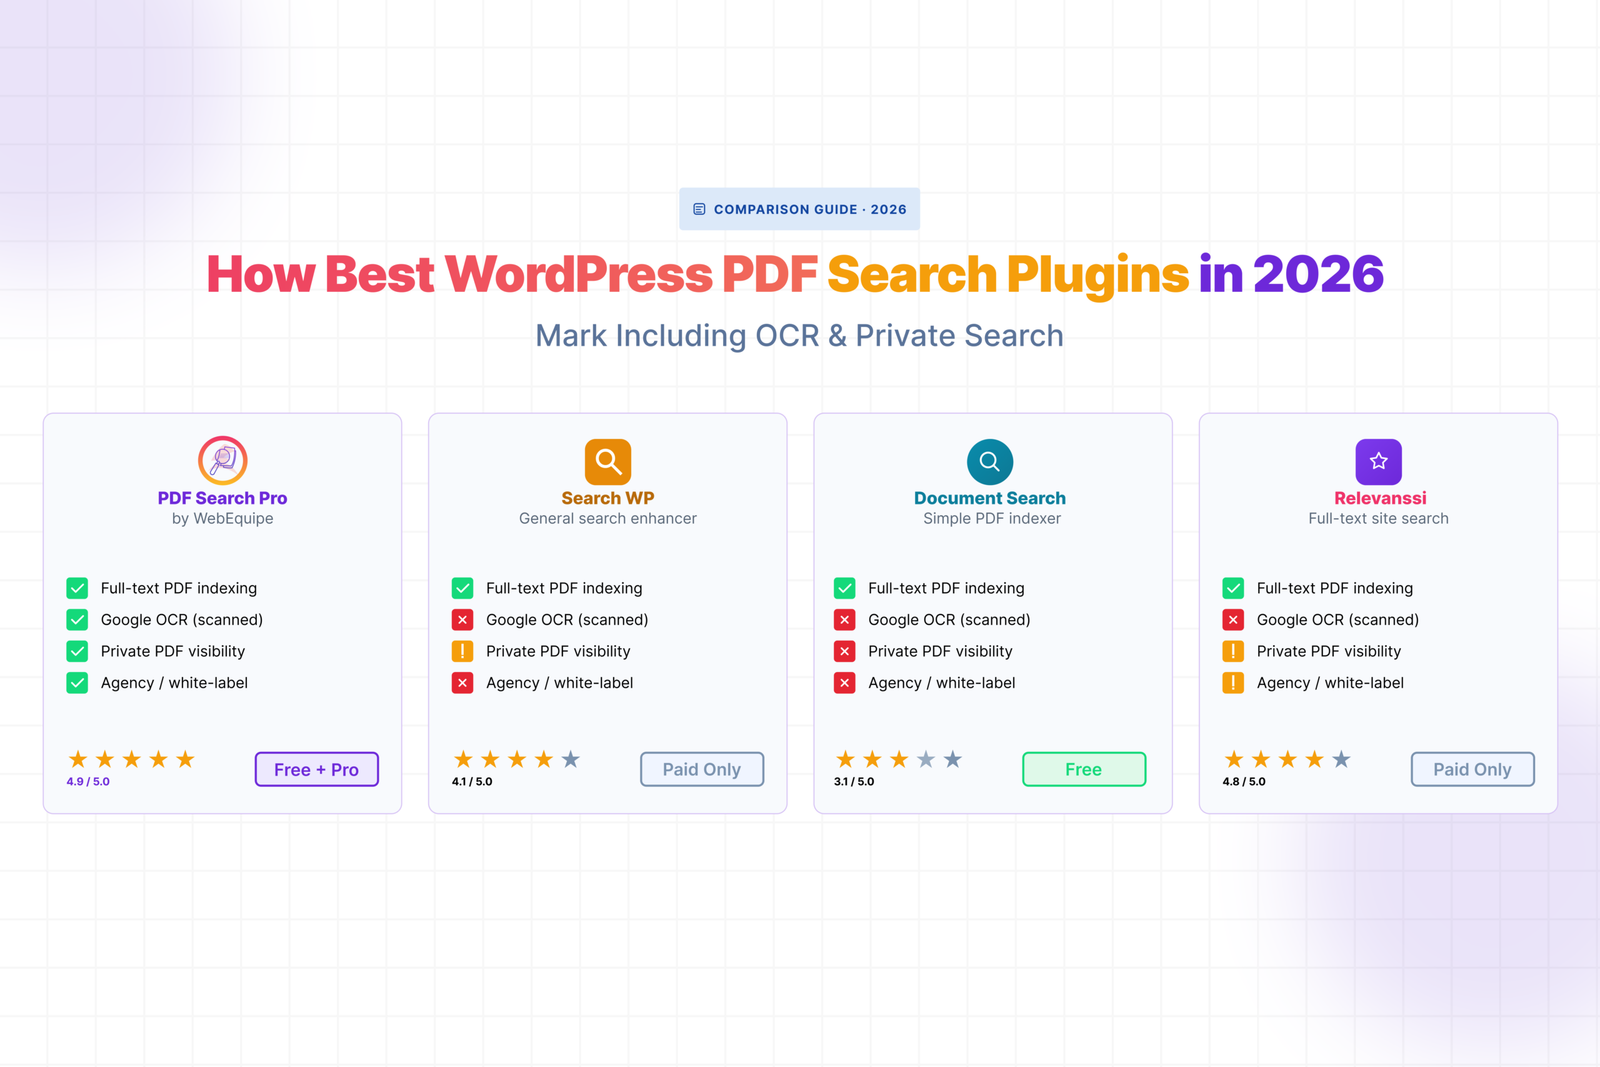
Relevanssi is one of the most popular WordPress search plugins for a good reason. It fixes the relevance problems that make default WordPress search frustrating — better ranking, fuzzy matching, AND-OR logic, highlighted excerpts. For sites where search quality matters, it’s a significant upgrade.
But if your problem is specifically that visitors can’t find content inside your PDF files, Relevanssi is solving a different problem. PDF support exists in the Premium version, but it’s not what the plugin was built around.
Here’s how the two compare for sites where PDFs are a primary concern.
What Relevanssi Does Well
Relevanssi replaces WordPress’s default search algorithm with a more sophisticated relevance engine. It weights matches differently depending on where the term appears — title, content, tags, comments — and lets you tune those weights. Search results feel more accurate because they are.
The free version already covers most of that. Fuzzy matching, AND search by default, search term highlighting in excerpts — all free. For a site where visitors struggle to find posts and pages because default search is too literal, Relevanssi free fixes most of it.
Premium adds PDF indexing, searching of user profiles and taxonomy descriptions, multi-site search, and a few other advanced features. It’s $99/yr and well maintained.
Where Relevanssi Falls Short for PDF-Heavy Sites
🟥 PDF support is Premium-only with no free tier
The free version doesn’t touch PDFs at all. If you want PDF content in search results you need Premium at $99/yr. For sites where PDF search is the only thing they’re after, that’s paying for a full search relevance engine to get document indexing.
🟥 No built-in OCR for scanned PDFs
Relevanssi Premium extracts text from PDF files directly. Scanned PDFs — image-based files with no text layer — can’t be indexed. There’s no OCR built in and no native path to index scanned documents without pre-processing them externally first.
For sites with historical archives, old meeting minutes, scanned handbooks, or government forms, this is a hard stop.
🟥 No private PDF search
Relevanssi doesn’t have a built-in mechanism for marking individual PDFs as visible only to logged-in users. Restricting document visibility requires a separate access control or membership plugin, and the integration isn’t always clean.
🟥 No per-file PDF management
Relevanssi doesn’t give you a dedicated screen for managing PDF index status. There’s no way to see which PDFs are indexed, which have failed, and why — at a per-file level. Diagnosing a PDF that isn’t showing up in search means working through general plugin settings rather than a document-specific workflow.
How WebEquipe PDF Search Compares
WebEquipe PDF Search is purpose-built for the PDF search problem. The free version indexes text-based PDFs, integrates with WordPress search, and gives you a full Media Library management screen with per-file status. No relevance tuning, no post/page search improvements — just PDF search done properly.
The Pro version adds OCR via Google Vision for scanned documents, Private PDF Search for logged-in-only visibility, and an Index Activity log that records every processing run with full error detail.
The two plugins are solving different problems. Relevanssi makes your whole site’s search better. WebEquipe makes your PDFs searchable — including the scanned ones.
These two plugins don’t conflict the way site-wide search replacements do. Relevanssi improves how WordPress searches posts and pages. WebEquipe adds PDF content to that search.
Running both is a clean setup for sites that need better relevance across all content AND proper PDF search. Relevanssi handles the ranking and relevance layer. WebEquipe feeds PDF content into the same search results.
The one thing to watch: both plugins hook into WordPress search results. Test the combined output after activating both to make sure PDF results are appearing and ranked sensibly alongside post results.
Who Should Use Which
🟥 Use WebEquipe PDF Search if:
Your main problem is that PDF content isn’t searchable at all
You have scanned documents that need OCR
You need to restrict certain PDFs to logged-in users
You want to start free and only pay for what you need
🟥 Use Relevanssi if:
Your search results feel irrelevant or miss obvious matches across posts and pages
You need fuzzy matching, AND/OR logic, or weighted relevance tuning
PDFs are a secondary concern and standard text-based documents are all you have
🟥 Use both if:
You want better search relevance across your whole site AND proper PDF indexing with OCR and private search support
Frequently Asked Questions
Does Relevanssi support scanned PDFs?
No. Relevanssi Premium extracts text from PDFs directly. Scanned PDFs have no text layer so they can’t be indexed without pre-processing the files externally. WebEquipe PDF Search Pro handles scanned documents automatically with built-in OCR.
Is Relevanssi free version enough for PDF search?
No. PDF indexing is a Premium-only feature in Relevanssi. The free version doesn’t index PDF content at all. WebEquipe PDF Search indexes text-based PDFs at no cost.
Can Relevanssi and WebEquipe run on the same site?
Yes. They complement each other well — Relevanssi improves relevance for posts and pages, WebEquipe handles the PDF-specific workflow. Test the combined search output after activating both to confirm PDF results appear correctly.
Which is better for a membership site with restricted PDFs?
WebEquipe PDF Search Pro. Private PDF Search lets you mark individual files as visible only to logged-in users without needing a separate access control plugin. Relevanssi doesn’t have an equivalent feature.
SearchWP is a well-built plugin. If you need to search across custom post types, WooCommerce products, custom fields, and ACF data all at once, it’s probably the right tool.
But if your main problem is that visitors can’t find content inside your PDF files — especially scanned documents or restricted member resources — SearchWP isn’t really built for that. PDF search is one line item in a long feature list, not the thing it was designed to solve.
Here’s where the gap shows up and what fills it.
What SearchWP Does Well
SearchWP replaces WordPress’s default search engine entirely. It gives you control over what gets searched, how results are weighted, and what content types appear. For sites with complex content structures — multiple post types, WooCommerce catalogues, lots of custom fields — that level of control is genuinely useful.
It indexes PDF content as part of its document search feature, available on the Professional plan. For standard text-based PDFs on a site that’s already using SearchWP for everything else, it works fine.
Where It Falls Short for PDF-Heavy Sites
🟥 No built-in OCR for scanned PDFs
SearchWP’s PDF indexing relies on extracting text from the file directly. If the PDF is a scanned document — a photograph of a page rather than digitally created text — there’s nothing to extract. SearchWP doesn’t have native OCR. You’d need to pre-process scanned files externally before they can be indexed, which means extra steps every time a scanned document gets uploaded.
For sites with a handful of scanned files this is manageable. For sites with archives of old reports, meeting minutes, government forms, or historical records, it becomes a real workflow problem.
🟥 No private PDF search
SearchWP doesn’t have a built-in way to mark individual PDFs as visible only to logged-in users. If you need member resources, staff handbooks, or restricted documents to be searchable only by people who are signed in, you’d need to handle that through a separate membership or access control plugin and hope the integration holds together.
🟥 PDF search requires the $199/yr plan
SearchWP’s PDF and document indexing is locked to the Professional plan. If PDF search is your primary need, you’re paying for the full search suite to get it — custom post type search, WooCommerce integration, metrics, live search — none of which you necessarily need.
🟥 No per-file status management
SearchWP doesn’t give you a dedicated screen showing which PDFs are indexed, which have failed, and why. If a PDF isn’t showing up in search, diagnosing the problem means digging through general search settings rather than looking at a per-file status log.
How WebEquipe PDF Search Fills the Gap
WebEquipe PDF Search was built specifically for the PDF search problem. Everything in it — the admin screens, the indexing workflow, the status management — exists because PDF search is the only thing it does.
🟥 OCR for scanned PDFs is built in.
On paid plans, Google Vision processes scanned documents automatically on upload. No pre-processing, no external tools, no extra steps. Scanned PDFs get indexed the same way as any other document.
🟥 Private PDF Search is a core feature.
Mark individual files as Private and they disappear from search results for logged-out visitors. Logged-in users find them normally. No membership plugin integration required.
🟥 The free version includes real PDF search.
Text-based PDFs, WordPress search integration, a shortcode form, and full Media Library management — all at no cost. You only pay when you need OCR or private search.
🟥 Per-file status is visible and actionable
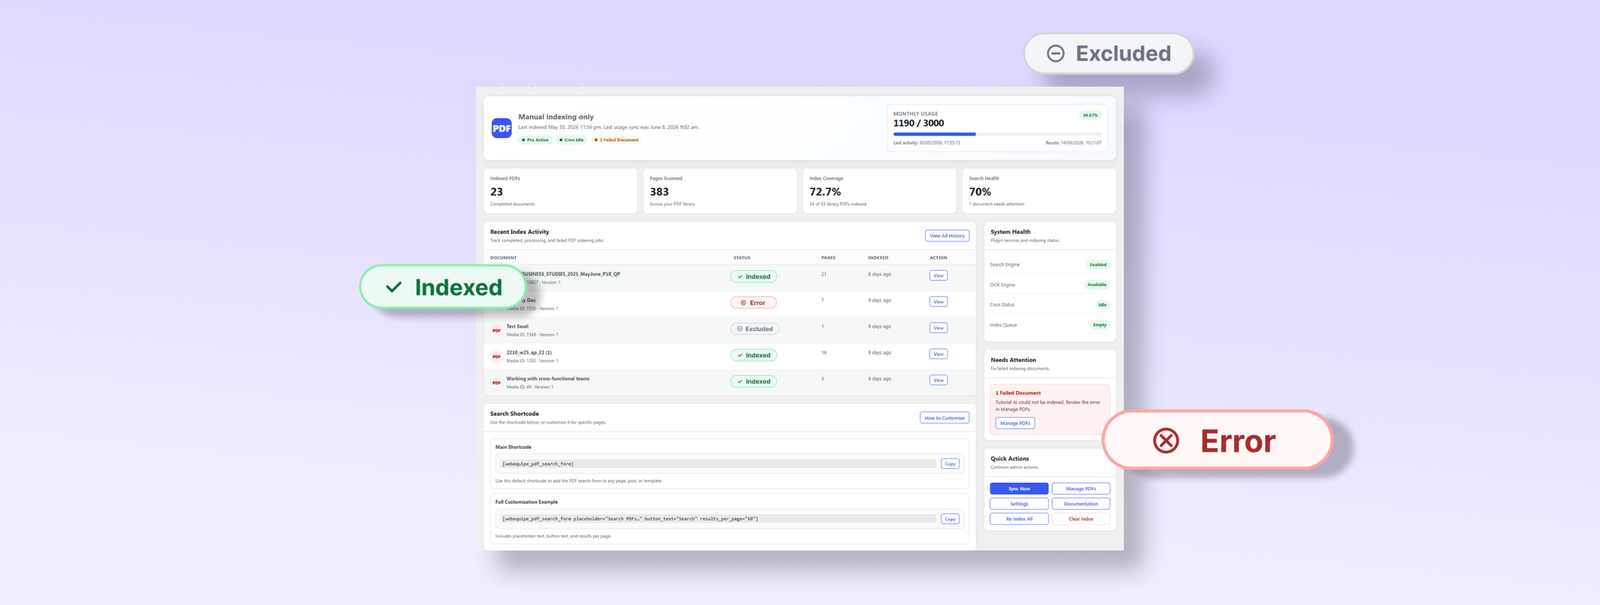
Every PDF in your library has a status badge — Indexed, Error, Excluded, Processing. The Index Activity log records every processing run with full error detail. When something goes wrong you can see exactly why.
Feature Comparison
WebEquipe PDF Search
SearchWP Professional
Text-based PDF indexing
✓ Free
✓ Paid ($199/yr)
Scanned PDF / OCR
✓ Paid (from $89/yr)
✕ Requires pre-processing
Private / logged-in-only PDFs
✓ Paid
✕
Per-file status management
✓
✕
Index Activity log
✓
✕
Free tier with PDF search
✓
✕
Full site search replacement
✕
✓
Custom post type search
✕
✓
WooCommerce search
✕
✓
Starting price
Free / $89/yr
$199/yr
Can You Use Both Together?
Yes — and for some sites this is the right setup.
If you’re already using SearchWP for site-wide search across posts, products, and custom fields, you don’t need to replace it. You can run WebEquipe PDF Search alongside it using the standalone shortcode form rather than the WordPress search integration.
This keeps SearchWP handling your general search while WebEquipe handles the PDF-specific workflow — OCR, private search, per-file status management — through a dedicated search form on your resources or documents page.
To avoid conflicts, leave Enable Search Integration off in WebEquipe PDF Search settings when running alongside SearchWP.
Use the [webequipe_pdf_search_form] shortcode for PDF search instead.
Who Should Switch and Who Shouldn’t
🟥 Switch to WebEquipe PDF Search if:
PDFs are your primary search problem and you don’t need site-wide search replacement
You have scanned documents that need OCR
You need to restrict specific PDFs to logged-in users
You want to start free and only pay when you need advanced features
🟥 Stick with SearchWP if:
You need to search across custom post types, WooCommerce, and ACF alongside PDFs
PDF search is one small part of a larger search overhaul
You’re already on SearchWP Professional and standard text-based PDFs are all you need
🟥 Use both if:
You need SearchWP for general site search and WebEquipe for OCR and private PDF search specifically
Frequently Asked Questions
Does SearchWP support scanned PDFs?
Not natively. SearchWP extracts text directly from PDF files. Scanned PDFs have no text layer, so they can’t be indexed without pre-processing the files externally first. WebEquipe PDF Search Pro handles this automatically with built-in OCR.
Is WebEquipe PDF Search cheaper than SearchWP for PDF search?
For PDF search specifically, yes. WebEquipe’s free version covers text-based PDFs at no cost. The Starter plan at $89/yr adds OCR. SearchWP’s PDF indexing requires the Professional plan at $199/yr.
Can WebEquipe PDF Search replace SearchWP entirely?
No — and it’s not designed to. WebEquipe is purpose-built for PDF search. It doesn’t replace site-wide search across custom post types, WooCommerce, or custom fields. If you need those, SearchWP is still the right tool for that job.
Will running both plugins cause conflicts?
Only if both are trying to modify WordPress search results at the same time. To avoid that, disable Enable Search Integration in WebEquipe PDF Search settings and use the shortcode form instead. SearchWP handles the main search, WebEquipe handles PDFs through its own form.
Most WordPress search plugins treat PDFs as an afterthought. They’ll index a filename, maybe a description field — but the actual text inside the document? Usually not.
If your site runs on documents — manuals, handbooks, reports, forms, catalogs — that gap matters a lot. Here’s an honest look at the plugins that actually solve it, what each one does well, and which situation each one fits.
What to Look for in a WordPress PDF Search Plugin
Before comparing options, it’s worth being clear about what the problem actually is. WordPress search doesn’t read PDF content by default. A plugin needs to do three things to fix that:
🟥 Extract text from the PDF.
This means opening the file and reading the content — not just the filename or metadata. For text-based PDFs this is straightforward. For scanned PDFs it requires OCR
🟥 Store that text in a searchable index.
Fast search requires the content to be pre-processed and stored, not read from the file on every query.
🟥 Surface results properly.
Showing a PDF title with no context isn’t useful. A good result includes an excerpt from the matching page so visitors know they’ve found what they’re looking for.
Beyond those basics, the things that separate good plugins from average ones are: how they handle scanned documents, whether they support private or restricted PDFs, how they manage large libraries, and what the admin workflow looks like when something goes wrong.
The Plugins Worth Considering
🟥 WebEquipe PDF Search
Purpose-built for PDF search. The free version handles text-based PDFs — auto-indexing on upload, WordPress search integration, a shortcode form, and a full Media Library management screen with per-file status.
The Pro version adds OCR via Google Vision for scanned documents, Private PDF Search for restricting files to logged-in users, and an Index Activity log that records every processing run with full error detail. Agency plan covers unlimited sites with white-label mode.
It’s the only plugin on this list built specifically around the PDF search problem rather than bolting it on to a broader search suite.
Best for: Sites where PDFs are the primary content — document libraries, resource centres, membership portals, government archives, product manual repositories.
Free plan: Yes — full text-based PDF search at no cost.
Paid plans: From $89/yr (Starter), $169/yr (Pro), $529/yr (Agency).
🟥 SearchWP
SearchWP is a full site search replacement that extends WordPress search across custom post types, custom fields, WooCommerce products, and documents including PDFs. PDF indexing is one feature among many.
It handles text-based PDFs reliably. Scanned PDF support requires a separate integration. The admin is comprehensive but reflects that breadth — there’s a lot to configure if you only need PDF search.
Pricing starts at $99/yr for the Standard plan. PDF document indexing requires the Professional plan at $199/yr.
Best for: Sites that need a complete search overhaul across multiple content types — not just PDFs.
🟥 Relevanssi
Relevanssi improves WordPress search relevance with better ranking, fuzzy matching, and highlighted excerpts. It’s widely used and well-maintained.
PDF indexing is a Premium feature. It extracts text from PDFs using external tools and adds them to the search index alongside posts and pages. There’s no built-in OCR for scanned documents.
The free version doesn’t include PDF support at all. Relevanssi Premium starts at $99/yr.
Best for: Sites that want better relevance and search quality across all content types, with PDF support as a secondary need.
🟥 WP File Download (JoomUnited)
WP File Download is a document management plugin that includes file search functionality. It handles multiple file types — PDFs, Word documents, spreadsheets — and provides a front-end file browser.
The search is file-content search rather than WordPress-native search integration. Results appear in its own interface rather than your site’s standard search results. PDF text extraction works for standard files; scanned document support isn’t a core feature.
Best for: Sites that need a full document library with browsing, filtering, and download management — not just PDF search.
You only need to search text-based PDFs and want to start free
WebEquipe PDF Search free version. Install it, run Re-index All PDFs, done. No paid plan required.
You have scanned documents that keep showing as Error
WebEquipe PDF Search Pro with OCR. It’s the only option here with built-in scanned PDF support that doesn’t require a separate integration or manual pre-processing.
You need PDFs restricted to logged-in users
WebEquipe PDF Search Pro. Private PDF Search is purpose-built for this — mark individual files as Private and they disappear from search for logged-out visitors.
You need to overhaul search across your entire site — posts, products, custom fields, and PDFs
SearchWP. It’s broader, more expensive, and more complex to configure — but it’s the right tool if PDF search is one piece of a larger search problem.
You want better search relevance across all content with PDF support as a bonus
Relevanssi Premium. Strong on relevance and ranking, PDF support is solid for standard documents.
You need a full document library with browsing, filtering, and multiple file types
WP File Download. Built for document management rather than search-first workflows.
A Note on Using Multiple Plugins Together
SearchWP and Relevanssi are site-wide search replacements. Running them alongside WebEquipe PDF Search on the same site can cause conflicts — both trying to modify the same WordPress search results.
If you’re already using SearchWP or Relevanssi for general search and only need to add PDF-specific features like OCR or private search, the cleanest approach is to use WebEquipe’s standalone shortcode form rather than the WordPress search integration. This keeps the two plugins out of each other’s way.
Frequently Asked Questions
Is there a free WordPress plugin that searches inside PDFs?
Yes — WebEquipe PDF Search. The free version indexes text-based PDFs and integrates with WordPress search at no cost. Scanned PDFs and private search require a paid plan.
Which WordPress PDF search plugin supports scanned documents?
WebEquipe PDF Search Pro is the only option on this list with built-in OCR for scanned PDFs via Google Vision. SearchWP can be extended with a third-party integration, but it’s not native.
Can I restrict PDF search results to logged-in users only?
WebEquipe PDF Search Pro includes Private PDF Search for this. No other plugin on this list has a built-in equivalent.
Do I need a paid plugin to search inside PDFs in WordPress?
Not for text-based PDFs. WebEquipe PDF Search is free for standard documents. You only need a paid plan for scanned PDF support (OCR) or logged-in-only visibility.
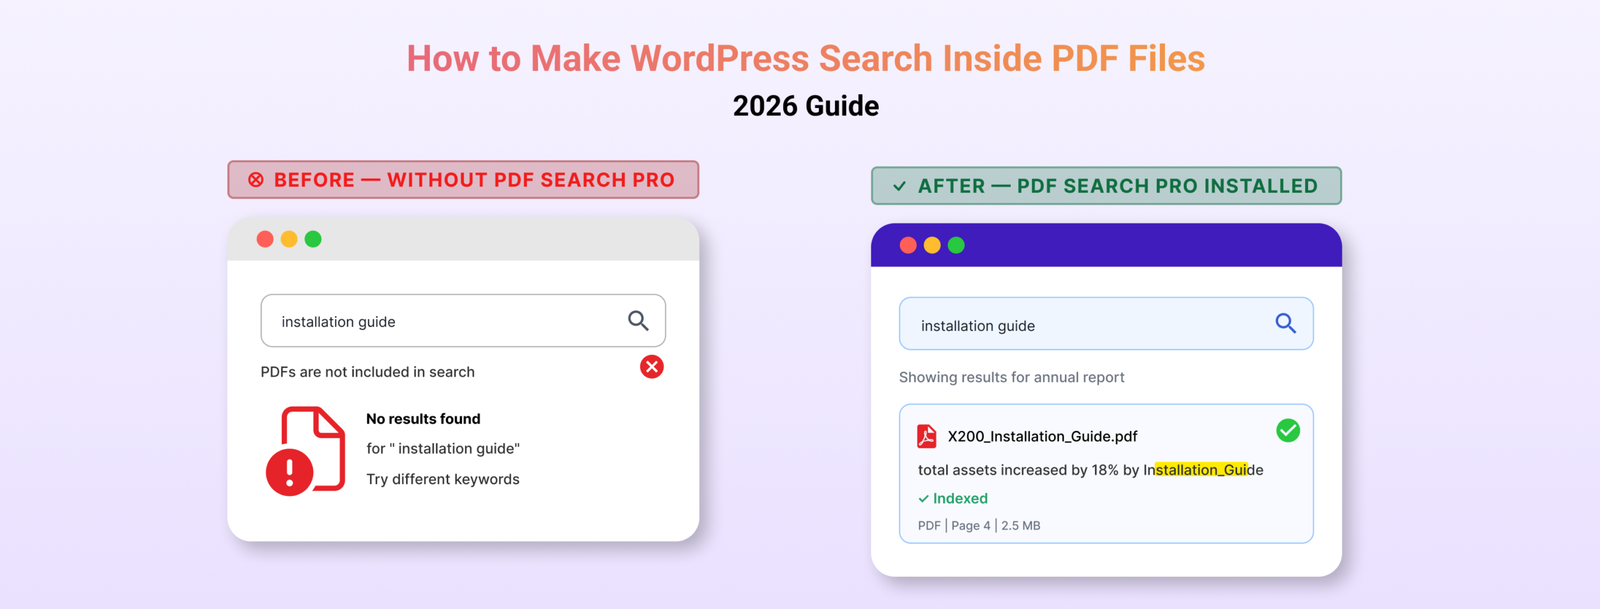
WordPress doesn’t search inside PDF files. Not by default, not ever. You can upload hundreds of documents and your site’s search bar will ignore every word inside all of them.
This guide covers everything — why it happens, how to fix it, how to handle scanned documents and private files, how to read your index activity, and what to do when things go wrong. If you manage PDFs on a WordPress site, this is the only reference you need.
WordPress search queries a single database table that stores post and page content. When you upload a PDF, WordPress records the filename, file size, and URL. That’s the extent of it. The text inside the file is never read, never stored, never searchable.
This isn’t something that gets fixed by tweaking settings or installing a general search plugin. You need a plugin specifically built to extract text from PDF files and store it in a searchable index. That’s what WebEquipe PDF Search does.
The Two Types of PDFs on Most Sites
Before setting anything up, it helps to know what you’re working with.
Text-based PDFs are created digitally — exported from Word, Google Docs, InDesign, or any document software. The text exists as real, selectable characters inside the file. Open one in your browser and you can highlight words, copy sentences, search the document. These are straightforward to index.
Scanned PDFs are photographs of physical pages saved as PDF files. The content is an image, not text. You can’t highlight anything inside them. A standard PDF search plugin marks these as Error because there’s nothing to extract.
Most document-heavy sites have both. Old archived reports, meeting minutes, forms designed for print — these tend to be scanned. Anything created or exported recently is usually text-based.
Knowing which type you’re dealing with determines which setup path you take.
Setting Up PDF Search — Free
The free version of WebEquipe PDF Search handles text-based PDFs. Install it, index your library, and your documents become searchable in minutes.
🟥 Install and activate
Go to Plugins → Add New, search for WebEquipe PDF Search, install and activate. A PDF Search menu appears in your WordPress admin sidebar.
🟥 Configure settings
Go to PDF Search → Settings and confirm two things are on:
Enable PDF Indexing — new uploads get indexed automatically when this is on. Every PDF you add to your Media Library gets processed without any extra steps.
Enable Search Integration — PDFs appear in your site’s standard search results alongside posts and pages.
If you want PDFs in a separate search form rather than mixed with posts and pages, you can leave Search Integration off and use the shortcode instead.
🟥 How auto-indexing works
With Enable PDF Indexing on, the moment you upload a PDF to your Media Library the plugin queues it for processing. For small files this happens immediately. For larger files — or if Background Processing is enabled — it queues and runs in the background so it doesn’t block the upload.
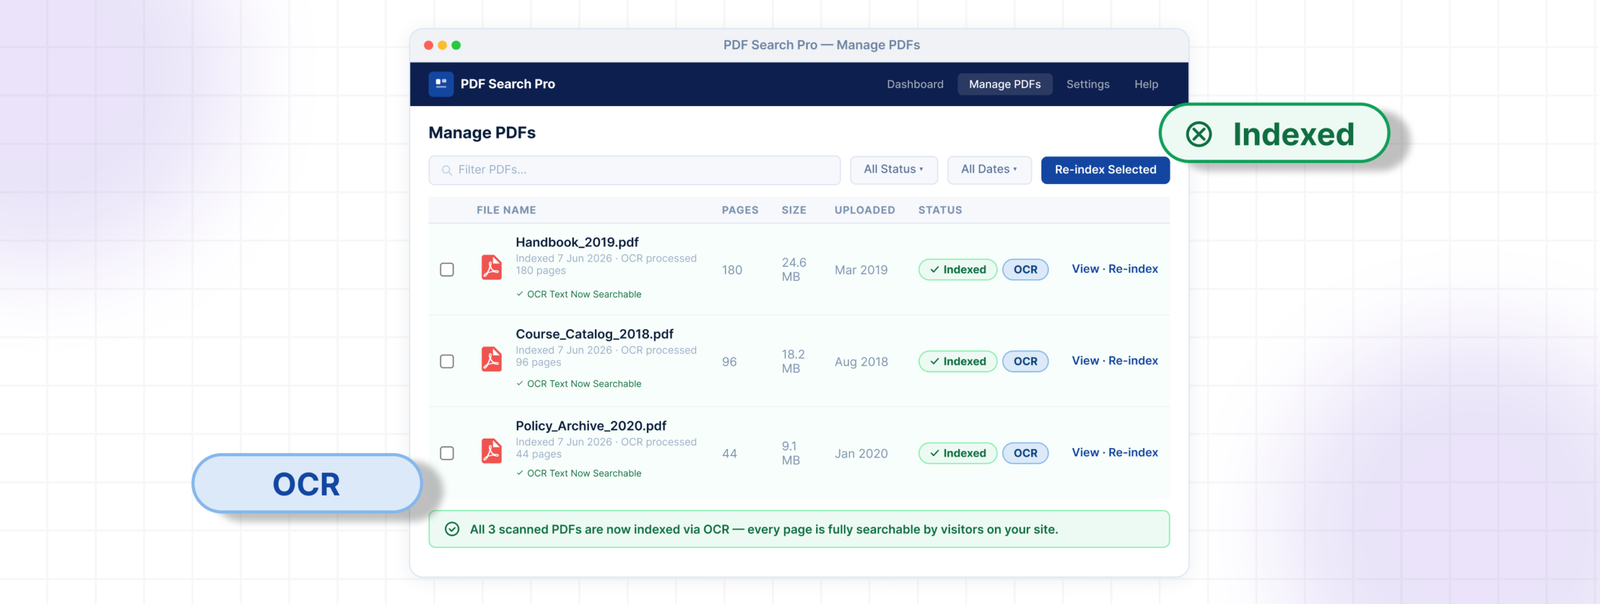
You’ll see the PDF status change from Not Indexed to Processing to Indexed in your Media Library column as it works through.
🟥 Index your existing library
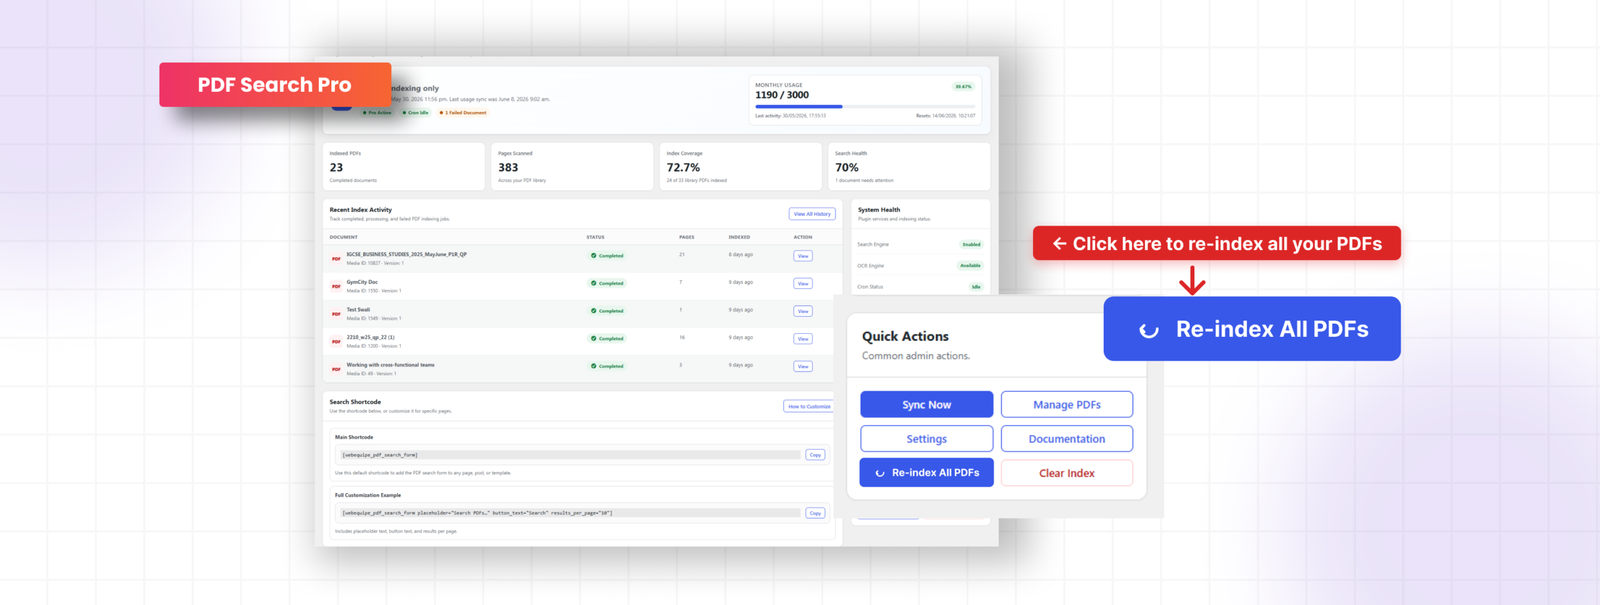
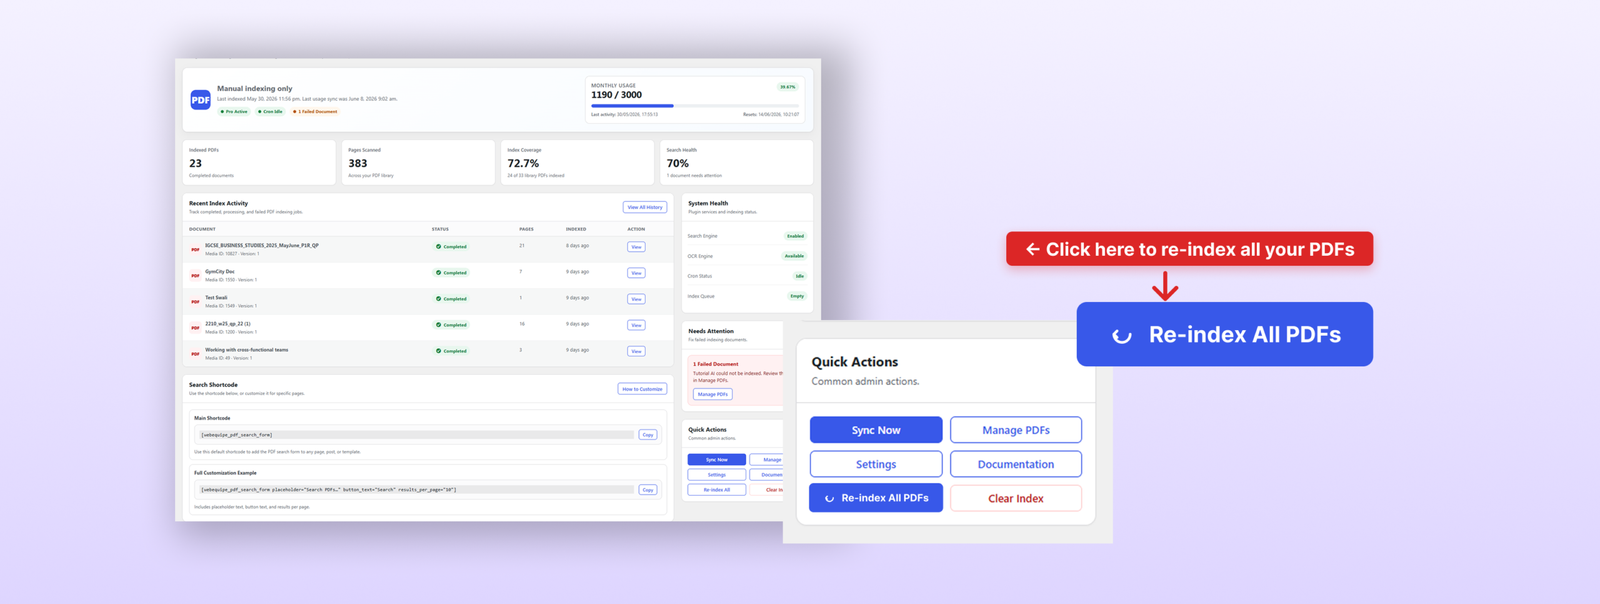
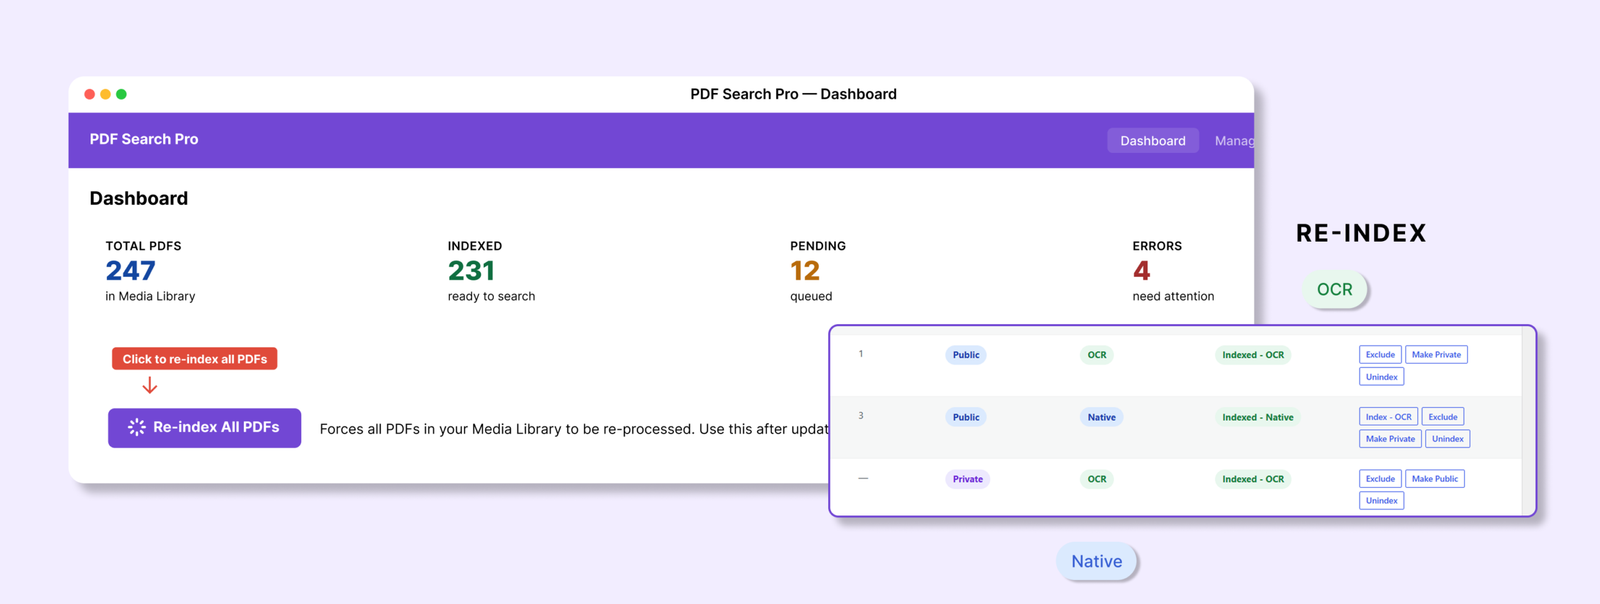
The plugin doesn’t automatically pick up PDFs already in your Media Library before it was installed. Go to PDF Search → Dashboard and click Re-index All PDFs. This processes everything in your library and builds the index from scratch. Large libraries run in batches in the background.
This searches only your indexed PDFs, completely separate from your site’s main search. Useful for resource centres, help sections, or document portals.
Dashboard Overview
PDF Search → Dashboard is your home screen. Here’s what everything means.
🟥 Metric cards at the top
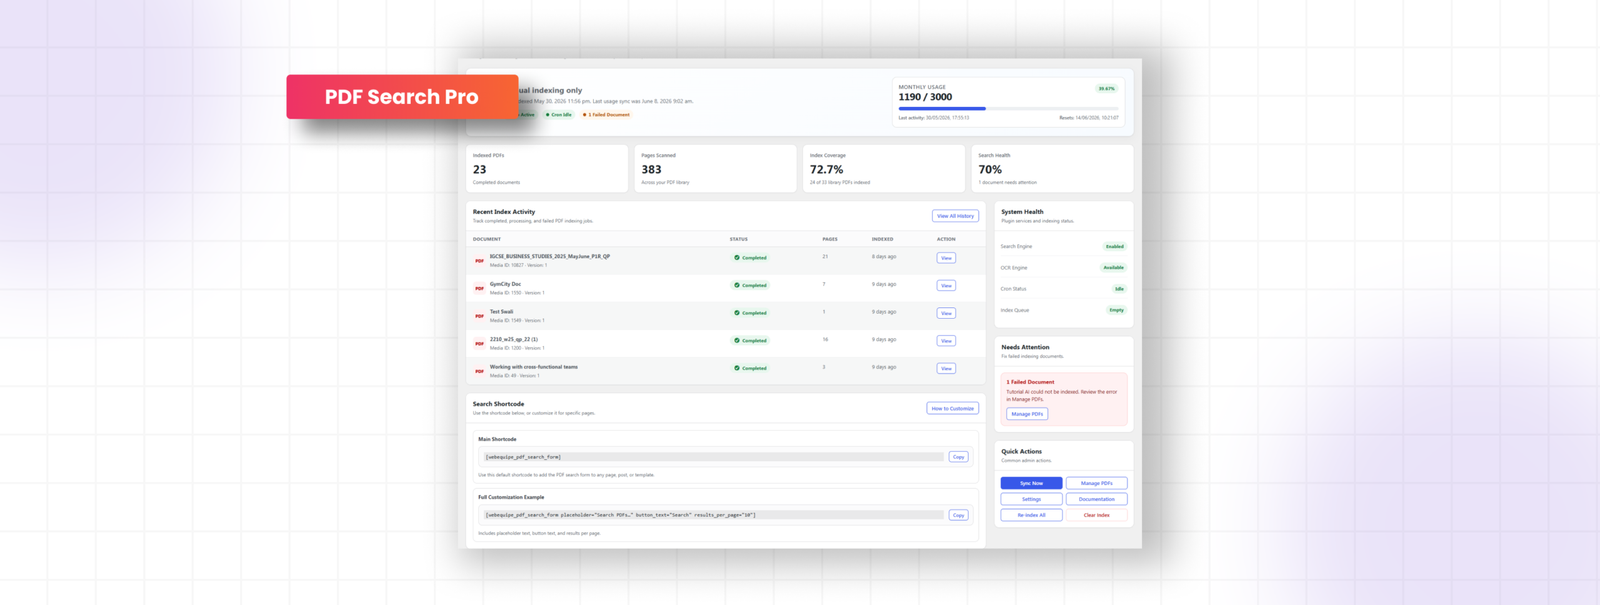
Metric cards at the top show indexed PDF count, total pages scanned, index coverage percentage, and search health status. Coverage tells you what proportion of your library is actually indexed — if it’s significantly below 100%, there are PDFs that need attention.
🟥 Status headline
Status headline gives you an at-a-glance reading of your setup — whether indexing is healthy, whether there are failed documents, and whether your cron is running correctly. If something needs attention it flags it here with a link directly to the problem.
🟥 Recent index activity
Recent index activity shows the latest indexing runs — which files were processed, when, and whether they succeeded. This is a preview of the full Index Activity log.
🟥 System health sidebar
System health sidebarshows your PHP version, memory limit, processing timeout setting, and cron status. If background processing is running slowly or failing silently, the cron indicator here is usually the first place that shows it.
🟥 Quick actions
Re-index All PDFs, go to Settings, go to Manage PDFs — are all accessible from the Dashboard without navigating away.
Handling Scanned PDFs with OCR
Scanned PDFs require OCR to be indexed. The plugin uses Google Vision — available on Starter, Pro, and Agency plans.
🟥 Set up OCR
Once your licence is active, go to PDF Search → Settings and set the Indexing Method to Native + OCR Fallback. Text-based PDFs get processed locally. Scanned files get routed to Google Vision automatically. You don’t decide per file.
🟥 Fix existing scanned PDFs
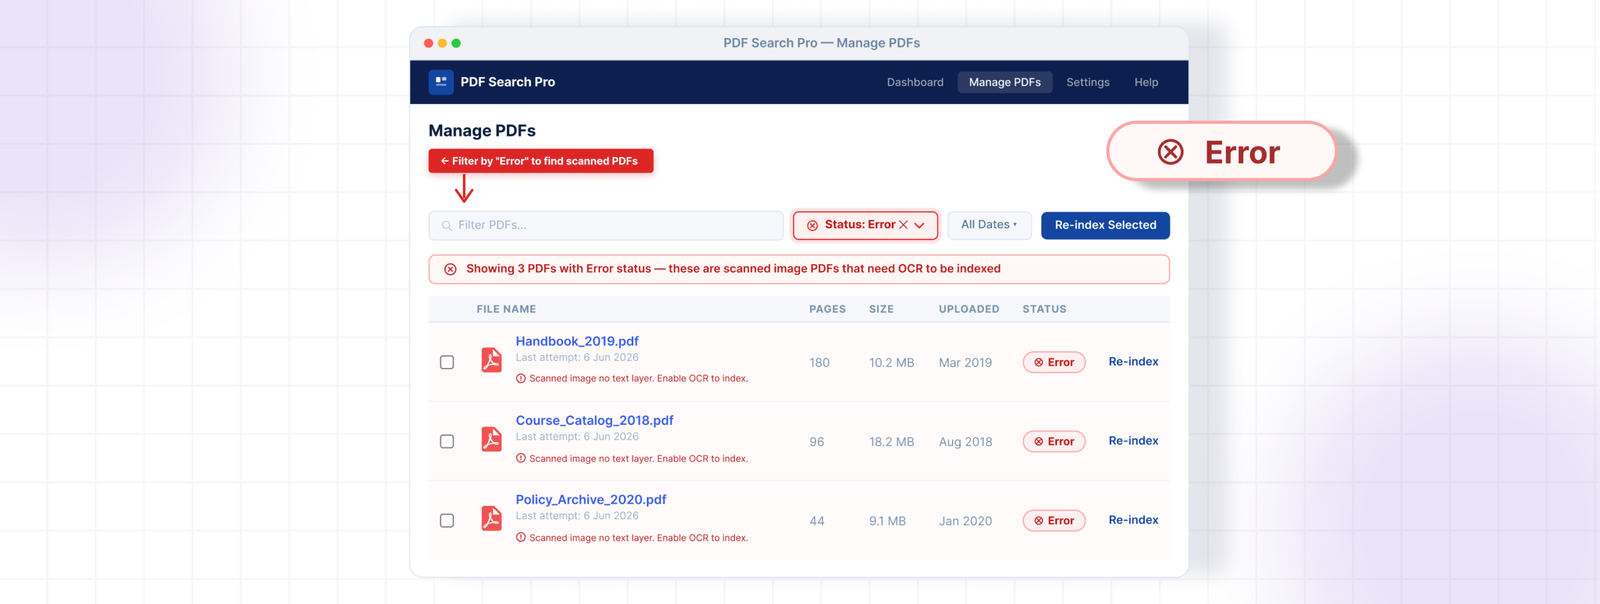
Go to PDF Search → Manage PDFs, filter by Error, select all the failed files, and run the bulk action Index OCR. Those files get sent to Google Vision and come back indexed.
🟥 OCR credits
Each plan includes a monthly page allowance — Starter gets 1,000 pages, Pro gets 3,000, Agency gets 10,000. Usage is visible in PDF Search → Dashboard.
Not every PDF on a site should be publicly searchable. There are two ways to handle this.
Exclude removes a PDF from search entirely. Nobody finds it — logged in or not. The file stays in your Media Library but is never indexed. Use this for drafts, outdated versions, and internal files that should never appear in any search results.
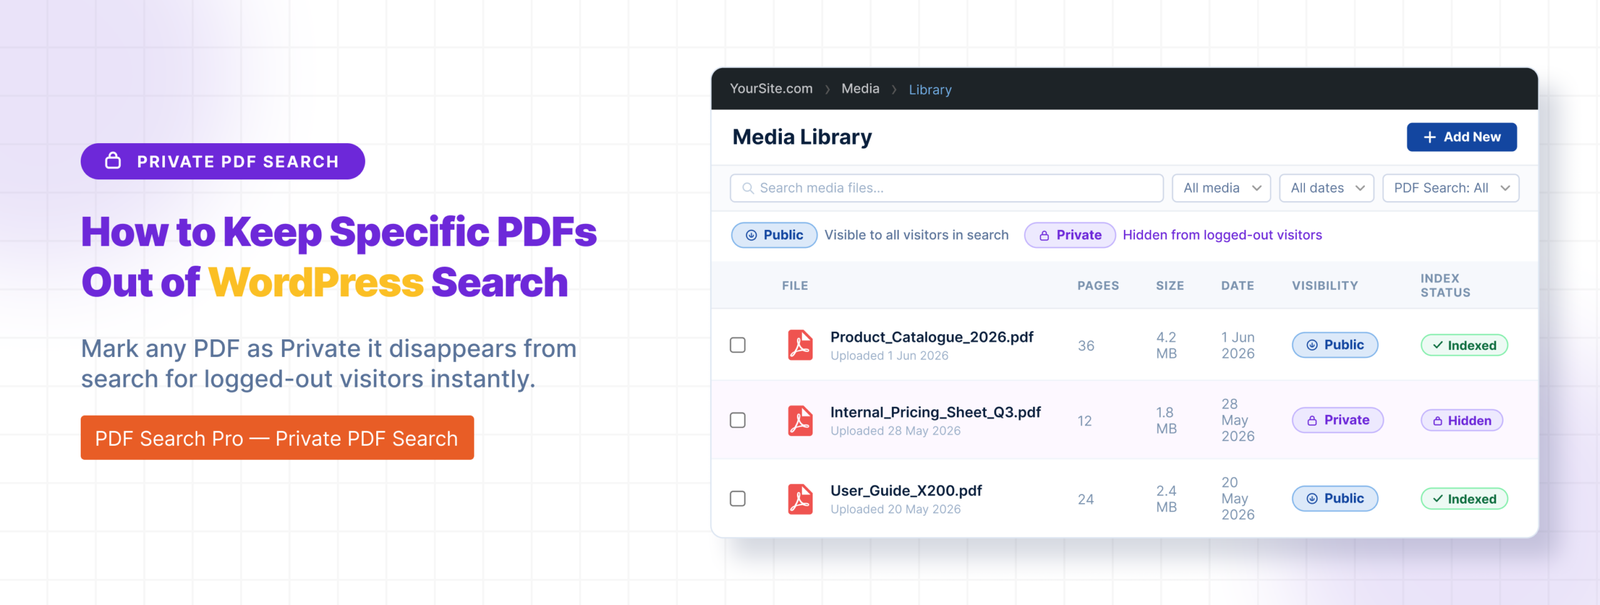
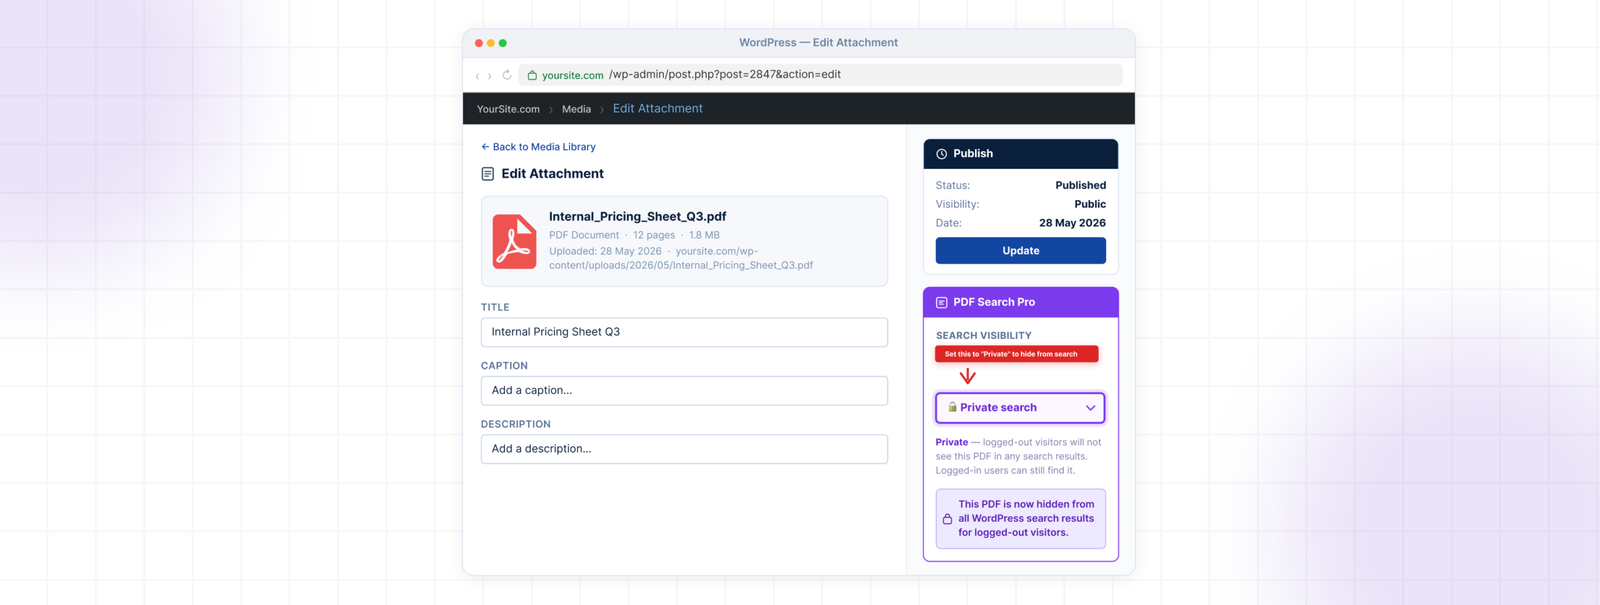
Private PDF Search keeps the PDF indexed but hides it from logged-out visitors. Logged-in users can still find it. Use this for member resources, staff documents, and restricted content that registered users need access to.
Exclude is available in the free plugin. Private PDF Search requires Pro or Agency.
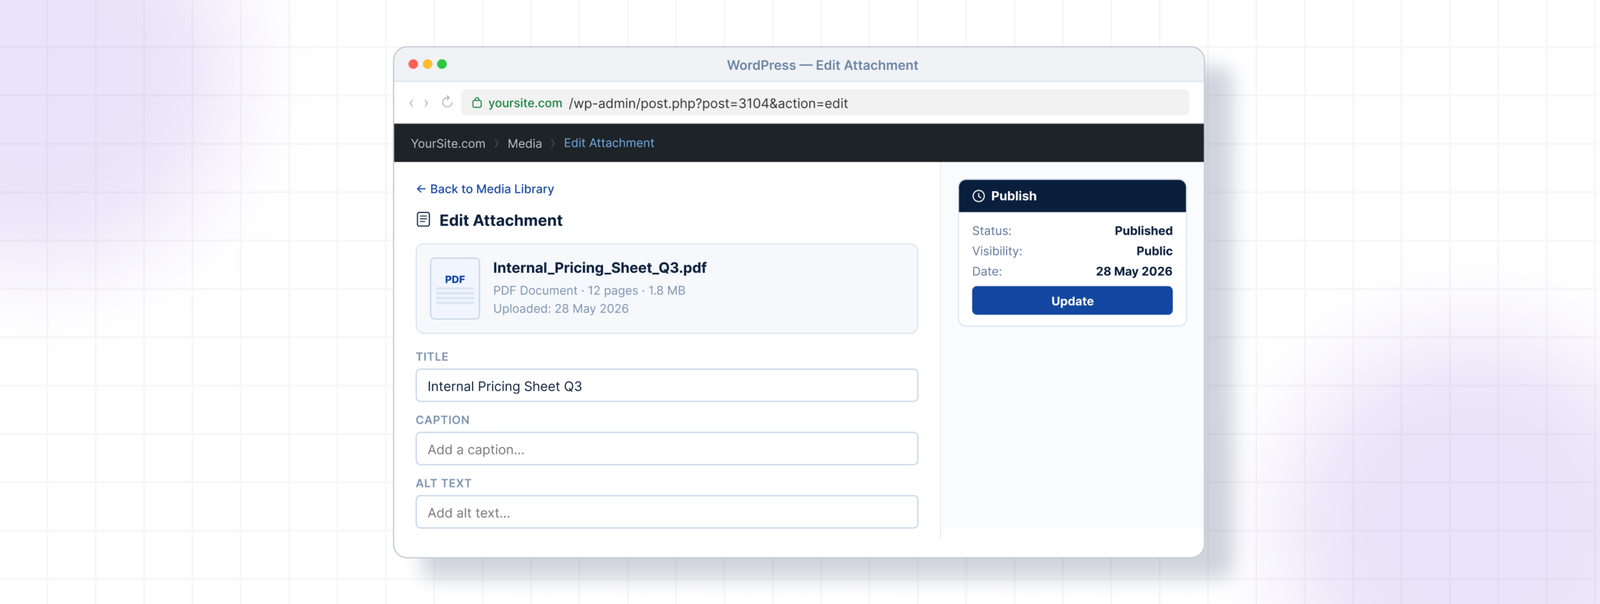
To exclude a PDF: open it in Media → Library, find the WebEquipe PDF Search panel, click Exclude.
To set a PDF to private: open it in Media → Library, set Search Visibility to Private, save.
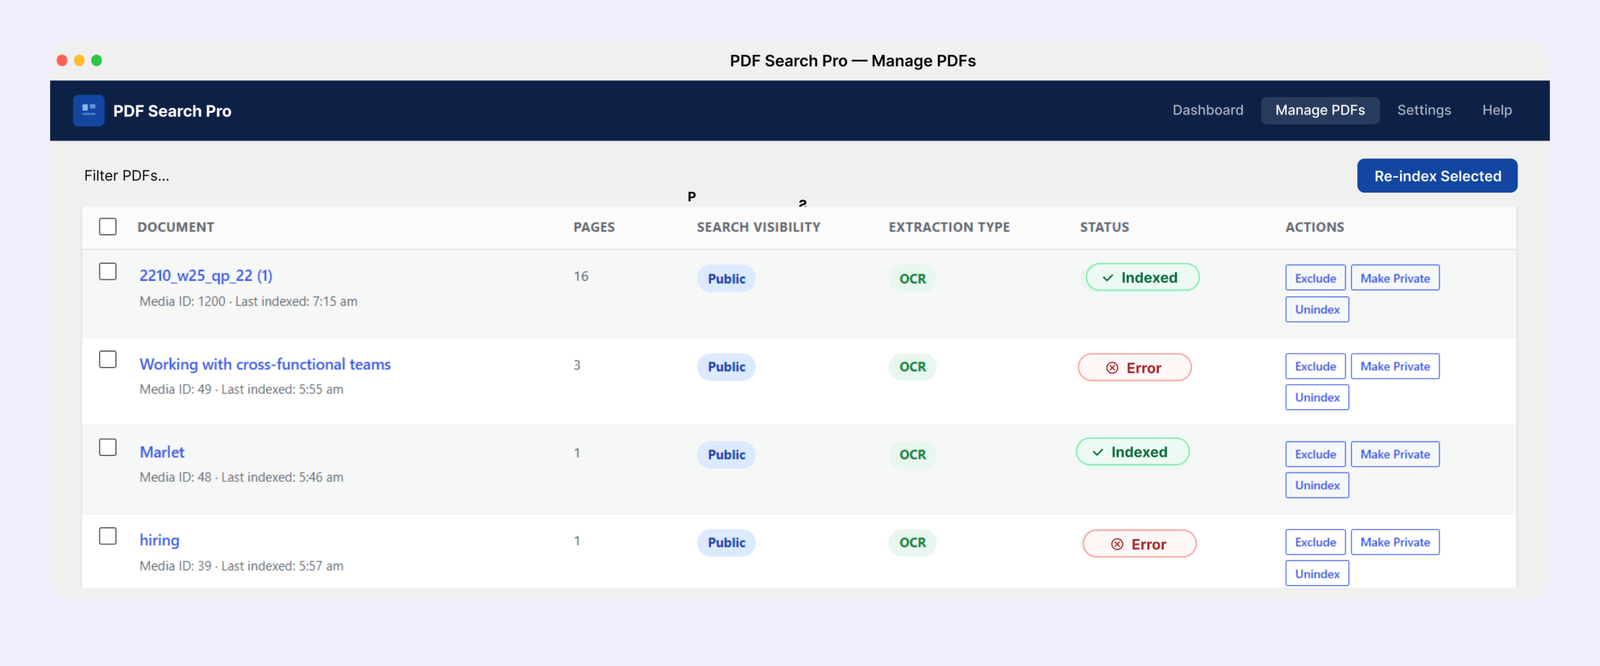
PDF Search → Manage PDFs gives you a full picture of everything in your library with filtering, bulk actions, and per-file controls.
Every PDF has a status badge:
Indexed — in search, working correctly
Not Indexed — in your library but not yet processed
Processing — currently being indexed
Scheduled — queued for background processing
Error — indexing failed, usually scanned or corrupted
Excluded — deliberately removed from search
🟥 Background processing
For large PDFs or libraries with many files, Background Processing moves indexing into a WP-Cron queue so it runs independently of the browser. Without it, a very large PDF can hit PHP execution limits mid-process and fail.
Enable it in PDF Search → Settings → Advanced → Enable Background Processing. Once on, PDFs above the page index threshold are automatically queued as Scheduled and processed in batches. You can leave the admin and come back — the queue runs on its own.
The batch size and page threshold are configurable in the same settings screen if you need to tune performance for your hosting environment.
🟥 Bulk actions
From Manage PDFs you can select multiple files and run: Index, Index OCR, Unindex, Exclude, Include, Make Public, Make Private. Useful for processing a filtered subset — for example, selecting all Error PDFs and bulk running Index OCR.
Index Activity
PDF Search → Index Activity is the full processing log — every indexing run recorded with timestamp, file name, status, page count, processing method, and duration.
🟥 Reading the log
Each row represents one indexing run for one file. The columns tell you:
File — which PDF was processed
Status — Completed, Processing, Failed, or Cancelled
Method — Native, OCR, or Partial (mixed PDF)
Pages — how many pages were indexed in that run
Time — when the run started and how long it took
If a run shows Failed, clicking the detail icon opens the full error message — exactly what went wrong and why. This is the fastest way to diagnose a stubborn file.
🟥 Statuses explained
Completed — processed successfully, content is indexed and searchable.
Processing — currently running. If a file stays in Processing for an unusually long time, it may have stalled — the Dashboard status indicator will flag this.
Failed — indexing did not complete. The error detail explains why — scanned file, corrupted PDF, timeout, file too large, password protected.
Cancelled — a run was interrupted, either manually or because a newer run was triggered for the same file.
🟥 Export log
The full activity log can be exported as a CSV from the top of the Index Activity page. Useful for auditing a large library, sharing with support, or keeping records of when specific documents were indexed.
Search Results — What Visitors See
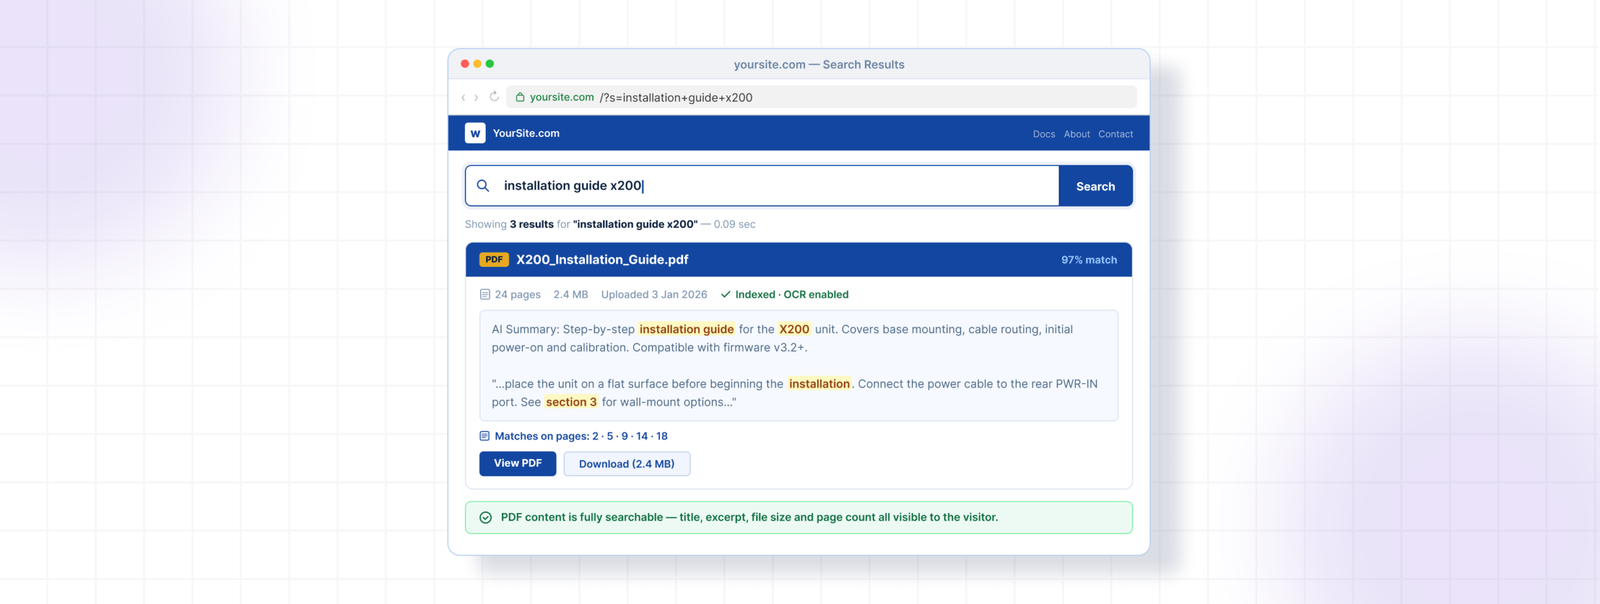
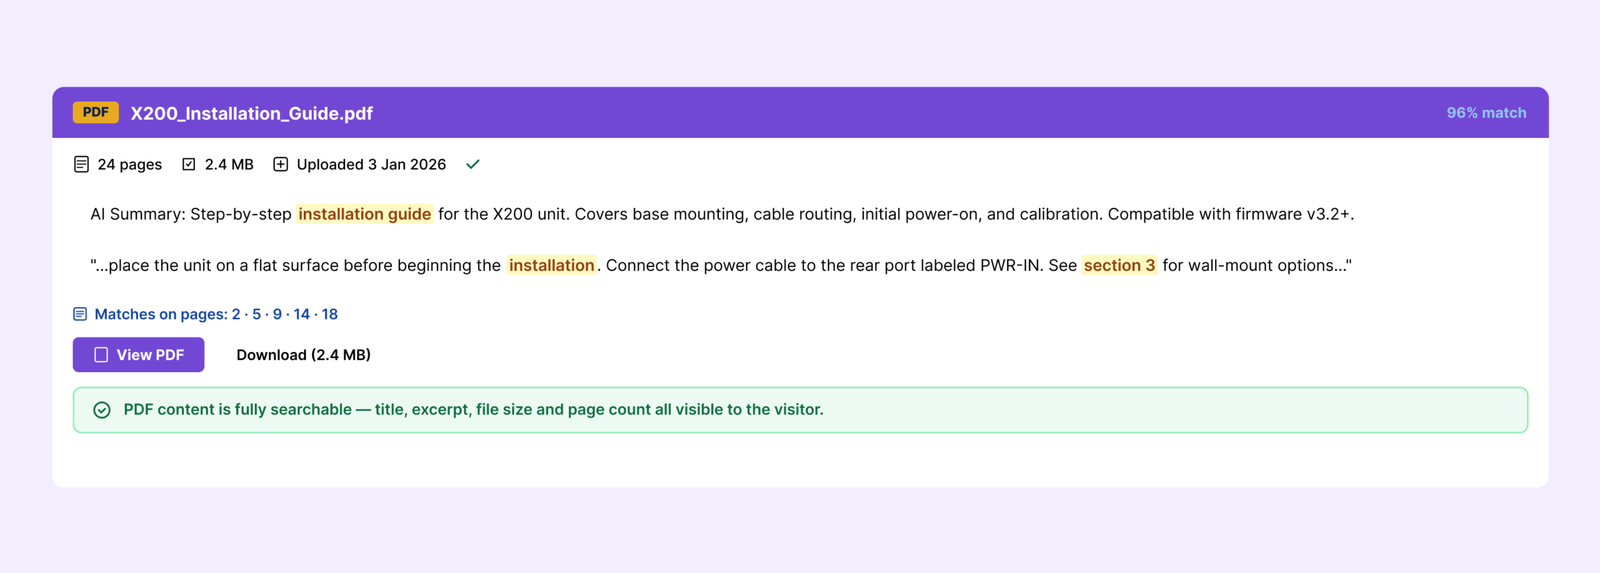
When a PDF appears in search results, visitors see the PDF title, a short excerpt from the best-matching page inside the document, file size, page count, and a direct link to open or download the file.
You can control which elements appear in PDF Search → Settings → Search Display Options. Icon, file size, page count, author, date, and excerpt can each be toggled independently.
Filenames become the displayed title in results. annual-report-2025.pdf is a lot more useful in search results than doc-v3-FINAL-revised.pdf — worth cleaning up filenames before indexing if yours are messy.
Common Problems and Fixes
PDFs not showing in search after indexing
Check that Enable Search Integration is on in PDF Search → Settings. Confirm the specific PDF isn’t Excluded.
Indexing keeps timing out
Enable Background Processing in PDF Search → Settings → Advanced. Large files need more time than a standard browser request allows.
PDFs show as Error
Almost always means the file is scanned. Filter by Error in Manage PDFs, select the files, run Index OCR. Requires a paid plan.
PDF appears in results but shows no excerpt
Text extraction returned very little content. Open the file and try to select text — if you can’t, it’s scanned.
Status stuck on Processing
The indexing job may have stalled. Go to Dashboard and check the cron status indicator. If cron is showing as disabled or broken, that’s the root cause.
Private PDFs showing in public search after licence expires
Private visibility is enforced by an active licence. Renewing restores the restriction immediately.
Free vs Pro — When to Upgrade
The free plugin covers text-based PDFs, auto-indexing, WordPress search integration, the shortcode form, Media Library management, and the full Index Activity log. For a lot of sites that’s everything they need.
Upgrade when:
You have scanned PDFs showing as Error — OCR is the only fix, it’s not in the free plugin
You need PDFs restricted to logged-in users — Private PDF Search requires Pro or Agency
You’re managing multiple client sites — Agency plan covers unlimited sites with white-label mode
No. WordPress only searches post and page content. PDF files are stored as attachments — WordPress reads the filename but never the text inside. A dedicated plugin is required.
Will PDF search slow down my site?
No. Indexing runs in the background. Search queries run against the stored index, not the original files. No impact on page load times for visitors.
How many PDFs can it handle?
No hard limit. Sites with several hundred PDFs run fine. Large libraries index in batches so nothing times out.
What happens to my indexed content if I uninstall the plugin?
By default nothing is deleted — your WordPress database keeps the index tables. If you want a full clean removal, enable Delete Data on Uninstall in PDF Search → Settings → Advanced before deactivating. This removes all plugin tables, options, and post meta on uninstall.
Does it work on WordPress Multisite?
Yes. Each site in a network has its own separate index, settings, and Index Activity log.
What PDF types are supported?
Text-based and mixed PDFs work with the free plugin. Scanned PDFs require OCR (paid plans). Password-protected and corrupted PDFs can’t be indexed by any method.
Does it work with my theme?
Yes. It hooks into WordPress’s native search, so it works with any theme using standard search. The shortcode form is theme-independent.
Where to Go From Here
The free plugin setup above covers the basics. Most sites are running in under ten minutes.
Not every PDF on your site should be searchable by everyone. Internal documents, draft files, member-only resources, staff handbooks — these need to stay out of public search results.
There are two ways to handle this in WebEquipe PDF Search, and they solve different problems. Using the wrong one causes its own issues, so it’s worth knowing the difference before you start.
Exclude vs Private — What’s the Difference
Exclude removes a PDF from search entirely. Nobody finds it — logged in or not. The file stays in your Media Library, but it’s never indexed and never appears in any search result. Even if you run Re-index All PDFs, excluded files get skipped.
Private PDF Search keeps the PDF indexed but hides it from logged-out visitors. Logged-in users can still find it through search. The file is fully searchable for your members, subscribers, or staff — just invisible to anyone who hasn’t signed in.
The right choice depends on what you’re trying to do:
🟥 Draft document that isn’t ready yet → Exclude
🟥 Outdated version you’re keeping for records → Exclude
🟥 Internal file that should never be public → Exclude
🟥 Member handbook your subscribers need to find → Private
🟥 Staff policy document for logged-in employees → Private
🟥 Client resource restricted to registered users → Private
How to Exclude a PDF
Exclude is available in the free plugin.
Go to Media → Library and open the PDF you want to exclude. In the WebEquipe PDF Search panel on the right side of the attachment screen, click Exclude.
The PDF is removed from the index immediately. If it was already showing in search results, it disappears. Running Re-index All PDFs in future will skip it automatically.
To reverse it, go back to the same panel and click Include, then re-index the file.
How to Set a PDF to Private
Private PDF Search requires a Pro or Agency licence.
Go to Media → Library and open the PDF. In the WebEquipe PDF Search panel, set Search Visibility to Private and save.
From that point, the PDF is invisible in search results for anyone not logged in. Logged-in users find it normally.
To confirm it’s working, open a private browsing window and search for the document title or a phrase from inside it. It shouldn’t appear. Log in and search again — it should show up.
Setting a Default Visibility for New PDFs
If most of your new uploads should be private by default, you can set that in PDF Search → Settings. Under Default Search Visibility, switch from Public to Private.
This means every new PDF you upload starts as Private. You can still change individual files to Public whenever needed.
What Private PDF Search Does Not Do
Private PDF Search is binary — logged in or logged out. It doesn’t restrict by user role, membership level, or subscription tier. A logged-in subscriber sees the same private PDFs as a logged-in administrator.
If you need per-role restrictions — showing certain PDFs only to specific membership levels or user groups — that’s on the roadmap but isn’t in the current version. For now, the combination of Exclude and Private covers most use cases.
Private PDF Search is available on Pro and Agency plans. The free plugin includes Exclude only.
No. Exclude only affects search indexing. The file stays in your Media Library and is still accessible via its direct URL. If you want to remove the file entirely, you’d delete it from the Media Library separately.
Can someone access a private PDF directly if they have the URL?
Yes. Private PDF Search only controls whether the file appears in search results. It doesn’t protect the file URL itself. If someone has a direct link to the PDF they can still open it. For full access control on the file itself, you’d need a file protection plugin alongside this.
Can I bulk set multiple PDFs to Private at once?
Yes. Go to PDF Search → Manage PDFs, select the files you want to restrict, and use the bulk action Make Private.
What happens to private PDFs if my Pro licence expires?
The PDFs stay in your library and stay indexed, but the Private visibility setting stops being enforced. They become visible in search results to everyone until the licence is renewed.
Can I make all new uploads Private by default?
Yes — set Default Search Visibility to Private in PDF Search → Settings. Individual files can still be switched to Public as needed.
The Right Tool for the Job
If a PDF shouldn’t be searchable by anyone, use Exclude. If it should be searchable only by logged-in users, use Private. Both are available from the same attachment panel in your Media Library — Exclude in the free plugin, Private in Pro.
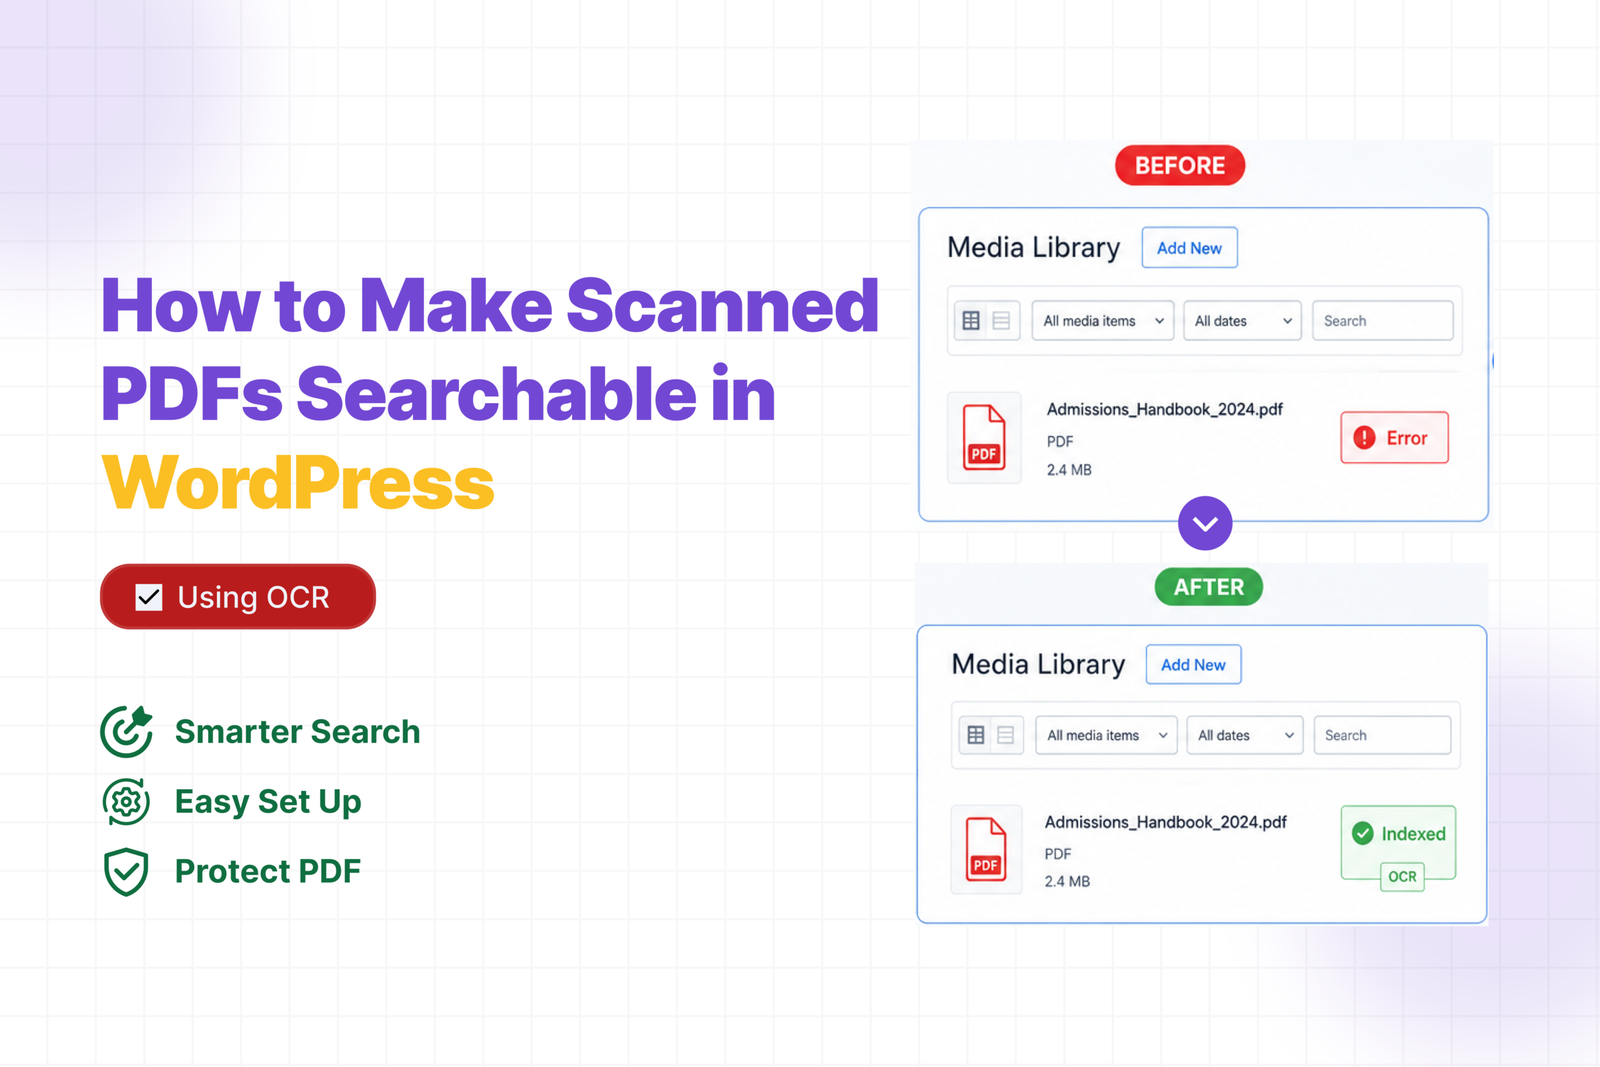
Your PDF search plugin is throwing Error on certain files because it’s trying to read a photo, not text. Scanned PDFs don’t have a text layer — they’re images of pages. There’s nothing to extract.
OCR fixes that. Here’s how to set it up.
Why Scanned PDFs Fail
When you export a PDF from Word or Google Docs, the text is stored inside the file as real characters. A search plugin opens it, reads the content, indexes it.
A scanned PDF is different. Someone put a physical page on a scanner and saved the result. What’s inside is a image of text, not text itself. Your plugin has nothing to work with, so it errors out.
You can confirm this in seconds — open the PDF in your browser and try to highlight some words. If you can select text, it’s text-based. If your cursor just draws a rectangle over the page, it’s scanned.
Setting Up OCR in WebEquipe PDF Search Pro
OCR is available on Starter, Pro, and Agency plans via Google Vision. Once your licence is active, here’s how to configure it.
Go to PDF Search → Settings. Under Indexing Method, set it to Native + OCR Fallback.
This is the right choice for most sites. The plugin tries standard text extraction first — faster, uses no OCR credits. If a PDF has no extractable text, it automatically sends it to Google Vision. Text-based PDFs get processed locally. Scanned ones get OCR without you having to decide per file.
If your library is almost entirely scanned documents, use OCR Only instead.
Fixing the PDFs Already in Your Library
Changing the indexing method doesn’t reprocess files that are already marked as Error. You need to trigger that manually.
Go to PDF Search → Manage PDFs and filter by Error status.
Select all of them and run the bulk action Index OCR. The plugin sends those files to Google Vision for processing. Depending on volume and file size this may take a few minutes — you can check progress in PDF Search → Index Activity.
Once done, those PDFs will show as Indexed with an OCR label. Search for a phrase from one of those documents to confirm it’s working.
A Few Things Worth Knowing
🟥 OCR uses credits. Each plan has a monthly page allowance — Starter gets 1,000 pages, Pro gets 3,000, Agency gets 10,000. Each scanned page uses one credit. Current usage is visible in PDF Search → Dashboard.
🟥 New uploads are handled automatically. Once OCR is enabled, any scanned PDF you upload going forward gets processed without extra steps. The plugin detects that standard extraction returned nothing and routes it to OCR.
🟥 Mixed PDFs index with a warning. If a PDF has some text pages and some scanned pages, the text pages index normally and the scanned ones get flagged. You’ll see a partial index warning in the status column.
🟥 Password-protected PDFs still can’t be indexed. OCR doesn’t help with locked files — the content isn’t accessible regardless of processing method.
Frequently Asked Questions
How do I know which PDFs are scanned?
Filter by Error in PDF Search → Manage PDFs after running a standard re-index. Any file that failed extraction is almost certainly scanned. You can also open individual files in your browser and try to select text.
How do I know which PDFs are scanned?
Filter by Error in PDF Search → Manage PDFs after running a standard re-index. Any file that failed extraction is almost certainly scanned. You can also open individual files in your browser and try to select text.
Will OCR work on handwritten documents?
Google Vision handles printed text reliably. Handwriting accuracy varies depending on legibility — worth testing on a sample before processing a large batch.
What happens when I hit my monthly OCR limit?
New scanned PDFs queue but don’t process until credits reset at the start of the next billing cycle. Existing indexed content stays searchable. You can upgrade your plan if you consistently need more capacity.
Can I use OCR on some PDFs and standard extraction on others?
Native + OCR Fallback handles this automatically. You don’t need to decide per file.
That’s the Fix
Filter your Error PDFs, bulk run Index OCR, and they’ll be searchable the same way any other document on your site is. For anything new coming in, Native + OCR Fallback takes care of it automatically from that point on.
Filter your Error PDFs, bulk run Index OCR, and they’ll be searchable the same way any other document on your site is. For anything new coming in, Native + OCR Fallback takes care of it automatically from that point on.
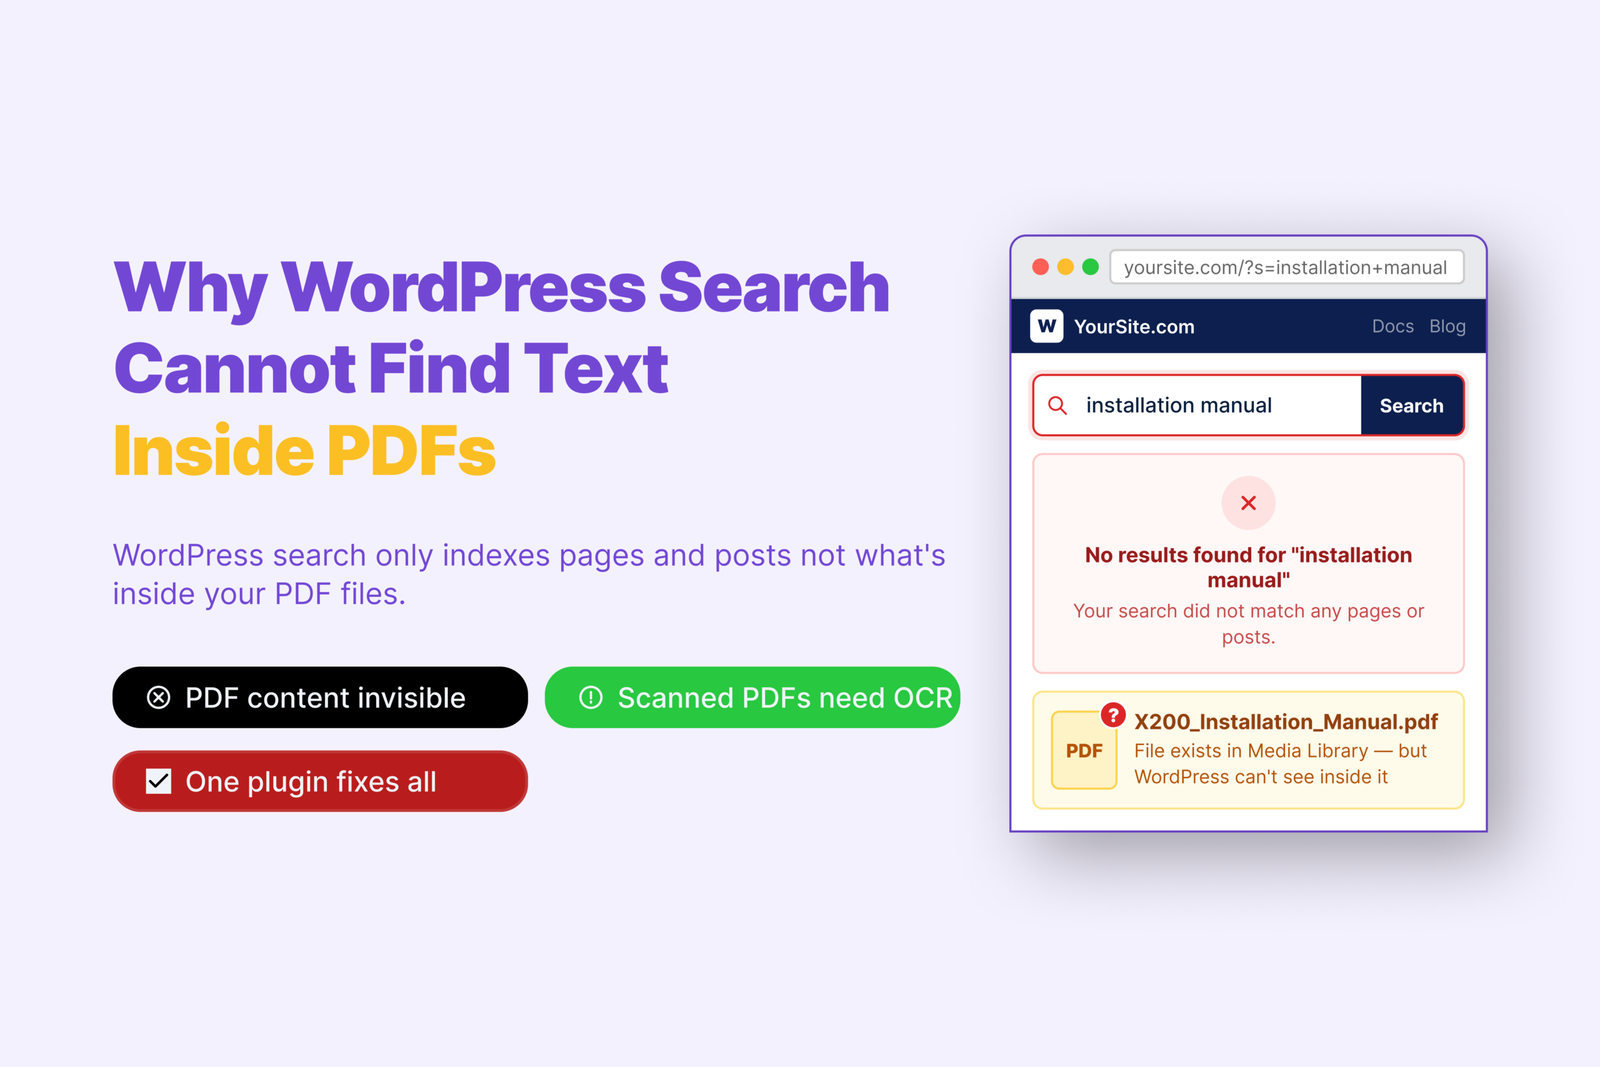
You search your own site for something you know is there. The word appears on page four of a PDF you uploaded last month. WordPress returns nothing. No results. Just that quiet, useless blank page. It feels like it should work. You uploaded the file. It’s sitting in your Media Library. Why can’t search find it? The answer is simpler than most people expect and so is the fix.
Why WordPress Cannot Find Text Inside PDFs
WordPress search works by looking through a specific table in your database — one that stores the content of your posts and pages. When you write a post or create a page, that content gets saved there and becomes searchable. PDFs work differently. When you upload one, WordPress saves the filename, the URL, and a few basic file details. That’s it. It never opens the file or reads what’s inside. So the actual text — the policies, the instructions, the answers your visitors are looking for — is sitting inside a file WordPress has never touched. It’s not a flaw. It’s just something WordPress was never built to do.
What’s Going Wrong — and How to Fix It
🟥 No PDF search plugin installed
Without a dedicated plugin, WordPress has no way to index PDF content. There’s nothing built in to do it. Install WebEquipe PDF Search from Plugins → Add New. It’s free. Once active, go to PDF Search→ Dashboard and click Re-index All PDFs.
That one step indexes everything in your Media Library and makes the content searchable. Test it straight after search for a phrase you know is inside one of your PDFs.
🟥 PDFs were uploaded before the plugin was installed
Plugins only pick up new uploads automatically from the point they’re activated. Anything already in your library needs to be indexed manually. Same fix — go to PDF Search → Dashboard and run Re-index All PDFs. One-time job.
🟥 Search integration is turned off
Some PDF search plugins index content but don’t automatically push results into WordPress search. There’s usually a separate toggle for this. Go to PDF Search → Settings and confirm Enable Search Integration is on. Without it, your PDFs are indexed but invisible in search results.
🟥 A specific PDF has a status problem
If most PDFs are working but one or two aren’t, the issue is with those files specifically — not the plugin setup. Go to PDF Search → Manage PDFs and look at the status badge on each file.
Not Indexed — hasn’t been processed yet. Click Index.
Excluded — deliberately removed from search. Click Include if it should be searchable.
Error — indexing failed. Usually means the file is scanned, corrupted, or password-protected.
🟥 The file is too large and timed out
Very large PDFs can hit PHP execution time limits mid-process. Indexing stops partway through and the file ends up in an error state. Go to PDF Search → Settings → Advanced and enable Background Processing. This moves indexing into a queue that runs independently — large files get the time they need without hitting server limits.
🟥 The PDF is a scanned document
Scanned PDFs — documents that were printed and photographed, or run through a scanner — are images packaged as PDF files. There’s no text layer inside. No standard plugin can read them. Open the PDF in your browser and try to highlight some text. If your cursor just draws a box over the image without selecting anything, it’s scanned.
Soft CTA
The free plugin can’t index scanned PDFs — that requires OCR. PDF Search Pro handles scanned documents automatically on upload, no extra setup needed.
Why does my PDF title appear in search but not the content inside it?
WordPress stores filenames and basic metadata for all media attachments, so the title can show up even when the content hasn’t been indexed. You need a PDF search plugin to actually read and index what’s inside the file.
I installed a plugin but my old PDFs still don’t show up.
Plugins only index new uploads automatically from the point they’re installed. For everything already in our library, run Re-index All PDFs manually from the plugin dashboard. One-time job, takes a few inutes depending on library size.
Some PDFs index fine but others show Error. What’s wrong with them?
Error almost always means the PDF is scanned with no text layer, or the file is corrupted or password-protected. Open it in your browser and try to select some text. If you can’t, it’s scanned and needs OCR.
My PDFs are indexed but still not appearing in search results.
Check that Enable Search Integration is turned on in your plugin settings. Also check the PDF isn’t set to Excluded. If both look fine, try searching for a very specific phrase you know is inside the document.
Can WordPress search inside password-protected PDFs?
No. A locked PDF can’t be read by any plugin. The file needs to be unlocked before it can be indexed.
Still Not Working?
Run through the fixes above in order — most cases resolve at the first or second step. If you’re stuck on scanned PDFs showing as Error, that’s not something the free plugin can solve. It genuinely needs OCR, and PDF Search Pro handles that without any extra setup.
If you’re starting fresh and want the full setup walkthrough:
You upload a PDF to WordPress. A visitor comes to your site, searches for something they know is in that document — and gets nothing back. No results. The file is sitting right there in your Media Library. The answer they need is on page three. WordPress just has no idea it exists. We hear this constantly from site owners. People who’ve done everything right — uploaded their documents, organised their library, built a decent site — and still can’t figure out why search ignores their PDFs entirely. The reason is straightforward once you know it. And so is the fix. Here’s both.
Why WordPress Search Ignores PDF Content
WordPress search works by looking at your posts and pages — the content you type directly into the editor. When you upload a PDF, WordPress stores the filename, a URL, and some basic file details. That’s all.
It never opens the file. It never reads what’s inside.
So when someone searches your site for “refund policy” or “installation guide” or “chapter three” — and those words only exist inside a PDF — WordPress comes back empty-handed. Not because the content isn’t there, but because it was never told to look inside PDF files.
This isn’t a bug. It’s just a gap that WordPress was never designed to fill.
What You Actually Need
To make WordPress search inside PDF files, you need a plugin that does two things.
First, it needs to extract the text from your PDFs. This means actually opening each file and reading the words inside — something WordPress doesn’t do on its own.
Second, it needs to store that text in a searchable index so that when someone types a query, it can match against that content.
A PDF search plugin fills that gap. There are a few options out there, but the simplest purpose-built one for WordPress is WebEquipe PDF Search. The free version handles standard PDFs and gets them into WordPress search in a few minutes. The Pro version adds OCR for scanned documents and private search for member-only content — more on those at the end.
Before You Start — Check Your PDFs
Not all PDFs are the same, and this matters before you install anything.
Text-based PDFs are documents created digitally — exported from Word, Google Docs, InDesign, or any document editor. These contain an actual text layer. A PDF search plugin can read them without any issues.
Scanned PDFs are photos of physical pages. Someone put a piece of paper on a scanner and saved the image as a PDF. There’s no text layer — just pixels. A standard PDF search plugin can’t read these.
How to tell the difference: open the PDF in your browser and try to highlight some text. If you can click and drag to select words, it’s text-based. If clicking just draws a box with nothing selected, it’s scanned.
The free plugin handles text-based PDFs well. If you have scanned documents, you’ll need OCR — covered at the end.
How to Make WordPress Search Inside PDF Files
Step 1 — Install WebEquipe PDF Search
Go to Plugins → Add New in your WordPress dashboard. Search for WebEquipe PDF Search. Install it and activate it.
Once it’s active, you’ll see a PDF Search item in your WordPress admin sidebar.
Step 2 — Check Your Settings
Head to PDF Search → Settings. You don’t need to change much here, but confirm two things:
Enable PDF Indexing is turned on — this makes sure new PDFs you upload get indexed automatically going forward.
Enable Search Integration is turned on — this is what makes PDFs show up alongside posts and pages in your site’s normal search results.
If you’d rather keep PDF results separate from your posts and pages, you can leave Search Integration off and use the shortcode instead (Step 5).
Step 3 — Index Your Existing PDFs
The plugin won’t automatically pick up PDFs you’ve already uploaded. You need to run indexing once for your existing library.
Go to PDF Search → Dashboard and click Re-index All PDFs.
The plugin will work through every PDF in your Media Library and extract the text. For a large library this runs in batches in the background — you can leave it and come back. Check the progress in PDF Search → Index Activity.
Step 4 — Test It
Once indexing is done, search for a word or phrase you know appears inside one of your PDFs.
It should now appear in results — with the PDF title, a short excerpt from the matching page, and basic file details like size and page count.
If a PDF isn’t showing up, go to PDF Search → Manage PDFs and check its status. Anything showing as Error or Not Indexed needs attention — the status badge tells you exactly why.
Step 5 — Add a PDF-Only Search Form (Optional)
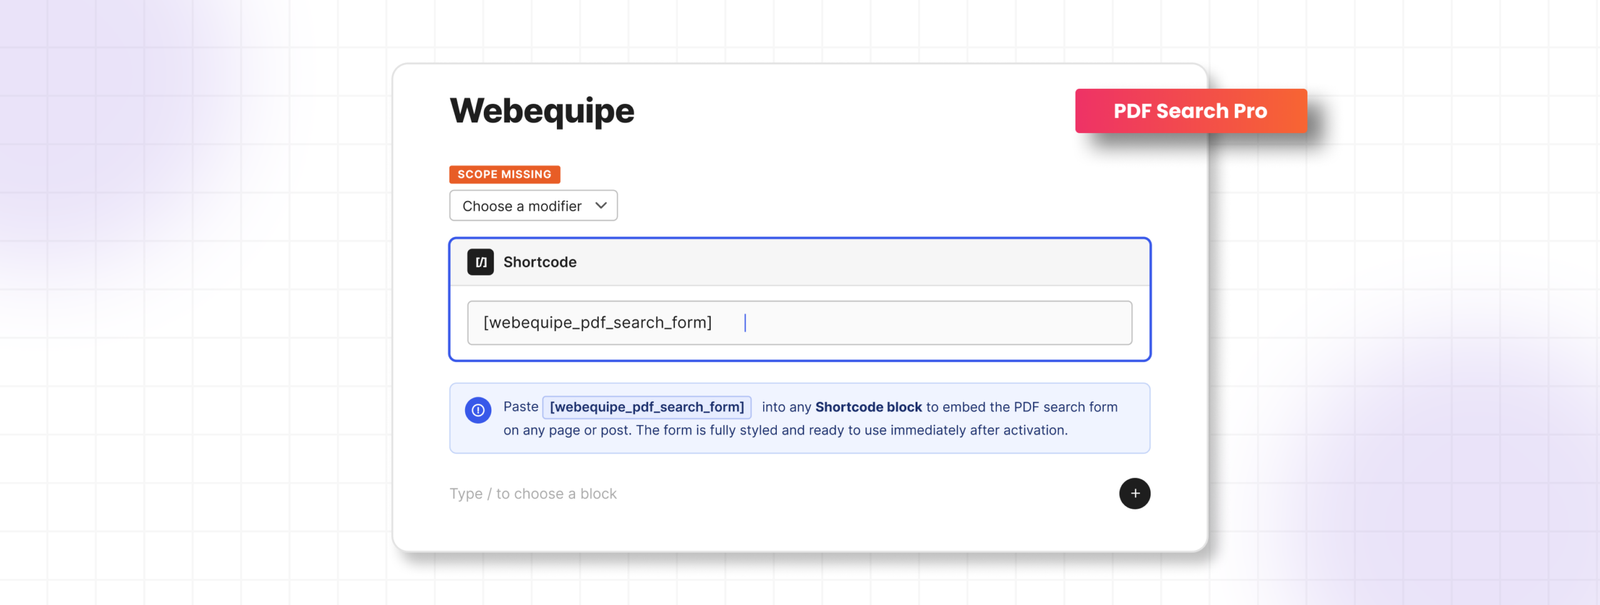
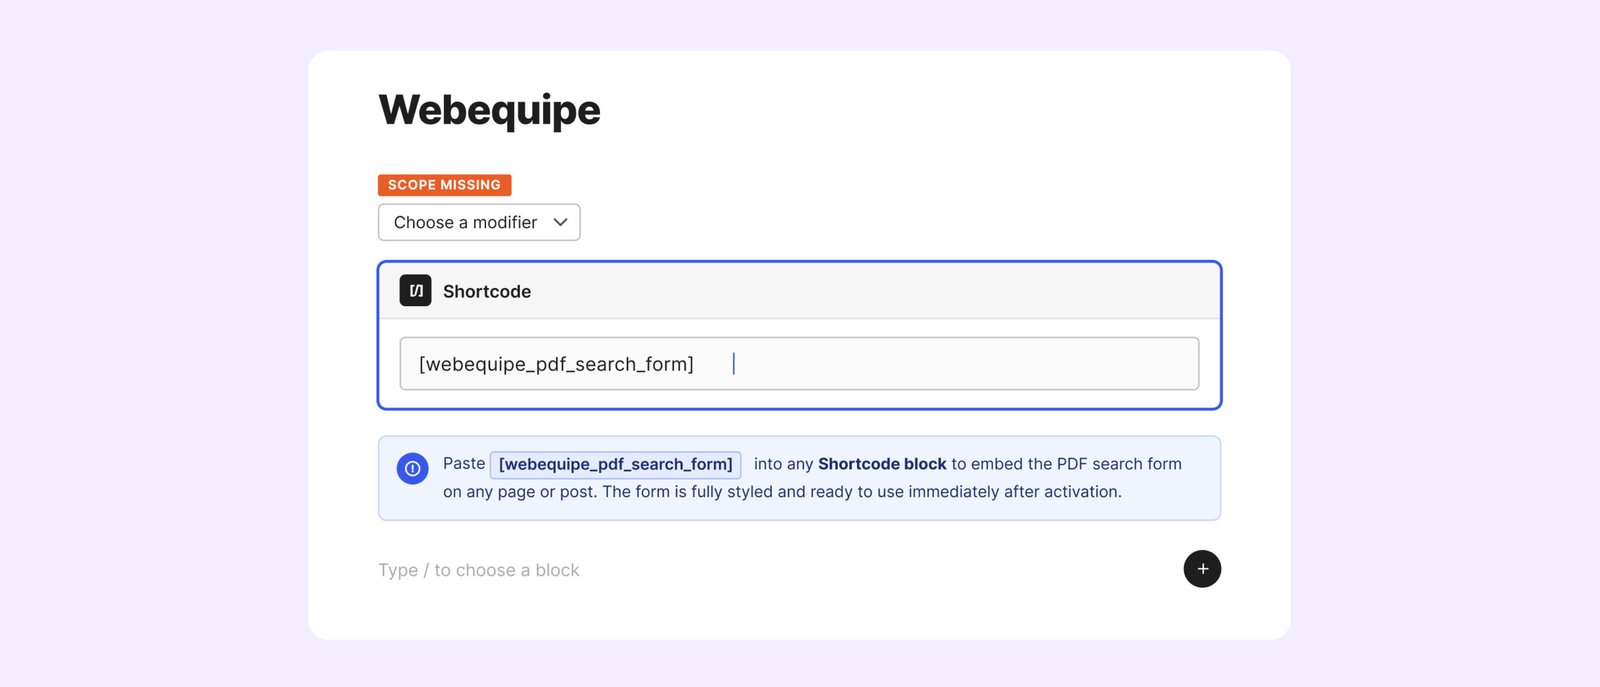
If you want a dedicated search box that only searches your PDFs — useful for help centres, resource libraries, or document portals — add this shortcode to any page:
Visitors get a search box that only looks at your PDFs — nothing else on the site, just the documents.
Soft CTA
The free plugin covers everything above at no cost. If you’re dealing with scanned documents or need to restrict certain PDFs to logged-in users only, that’s what PDF Search Pro is built for.
Best Practices
Filenames become titles. In search results, the PDF’s filename is what gets displayed as the title. annual-report-2025.pdf is a lot more useful than doc-final-v2-FINAL.pdf. It’s worth cleaning up filenames before you index.
The index doesn’t update automatically when you replace a file. If you swap out a PDF for a newer version, you need to manually re-index that file. Go to it in your Media Library and click Re-index.
Use Exclude for PDFs that shouldn’t be searchable. Draft documents, internal files, outdated versions — use the Exclude option on these. The file stays in your Media Library, it just won’t be indexed or show up in any search results.
Large files take longer. The default size limit is 50MB. You can raise this in settings up to 500MB. Very large PDFs are processed in background batches automatically so they don’t time out.
Common Problems and How to Fix Them
PDFs still aren’t showing up after indexing
Check that Enable Search Integration is on in PDF Search → Settings. Also confirm the specific PDF isn’t set to Excluded.
Indexing keeps stopping or timing out
Go to PDF Search → Settings → Advanced and turn on Background Processing. This moves indexing out of the browser and into a background queue so it doesn’t need to finish in a single page load.
Some PDFs index fine but others show Error
This almost always means those PDFs are scanned — image-only files with no text layer. The free plugin can’t read them. You’ll need OCR for those.
PDFs show in results but with no excerpt
Usually means the text extraction returned very little content. Try opening the PDF and selecting some text. If you can’t highlight anything, it’s likely a scanned file.
When the Free Plugin Isn’t Enough
The free plugin handles text-based PDFs well. But two situations need the Pro version.
You have scanned PDFs
Archived reports, meeting minutes, old handbooks, government forms — these are all image-only files. The free plugin marks them as Error because there’s no text to extract.
WebEquipe PDF Search Pro includes OCR powered by Google Vision. Turn it on and scanned PDFs get processed automatically when you upload them — the text gets pulled from the images and indexed the same way a normal PDF would be. Nothing extra to set up on your end.
You need some PDFs visible only to logged-in users
The free plugin’s Exclude feature removes a PDF from search entirely. But sometimes you want a document findable — just not by everyone. Member handbooks, staff policies, client resources.
Private PDF Search (available on Pro and Agency plans) lets you mark individual PDFs as Private. They stay indexed but disappear from results for anyone who isn’t logged in. Logged-in users find them normally.
Frequently Asked Questions
Does WordPress search inside PDFs by default?
No — and this surprises a lot of people. WordPress only searches content you’ve typed directly into posts and pages. PDF files are stored as attachments. WordPress knows the filename exists but has never looked inside it. That’s what the plugin fixes.
Will this slow down my site?
Not in any noticeable way. Indexing happens in the background, either when a PDF is uploaded or when you manually kick it off. When someone searches, the query runs against the stored index — not the original files. Your visitors won’t feel a thing.
What about PDFs I’ve already uploaded?
Those won’t be picked up automatically. You run Re-index All PDFs once from the Dashboard after installing the plugin and it processes everything in your library. New uploads after that are handled automatically.
Can it handle password-protected PDFs?
No. If a PDF is locked, the plugin can’t get to the text inside it. Those files need to be unlocked before they can be indexed.
How many PDFs can it handle?
No hard limit. We’ve seen it work fine on sites with several hundred PDFs. Large libraries just run in batches so nothing times out.
Does it work with my theme?
Yes. It plugs into WordPress’s native search, so any theme using standard WordPress search will show PDF results. The shortcode form works independently of your theme entirely.
Getting Your PDFs Into Search
If your site has text-based PDFs, you’re ten minutes away from having them fully searchable. Install the free plugin, run Re-index All PDFs once, and your documents will start showing up in results straight away.
If you’re dealing with scanned files or need to keep certain documents restricted to logged-in users, that’s exactly what PDF Search Pro is built for.
Two types of PDFs exist on most WordPress sites — only one is searchable by default. Most site owners don’t know which of their PDFs are scanned. This guide explains the difference, how to check, and how to make scanned documents searchable.
The Difference Between Text PDFs and Scanned PDFs
Text-based PDF: created digitally in Word, Google Docs etc. Contains actual text layer. Any search plugin can read it.
Scanned PDF: a photograph of a physical page. No text layer. Just pixels.
How to tell: open PDF in browser, try to select text. If you can highlight words → text-based. If selection draws a rectangle → scanned.
Why Scanned PDFs Are Invisible to WordPress Search
WordPress search queries post_content field
PDF plugins extract text from PDFs and store it
Extraction works by reading the text layer
Scanned PDFs have no text layer — extraction returns empty