πŸŽ‰ Save 10% Extra on the Webequipe PDF Search Plugin Annual Plan β€” Use code YEARLY10 Β· Limited-time offer Β· Get discount β†’

What I’d Check on Every WordPress Site Before Calling Its PDF Section Done

What I'd Check on Every WordPress Site Before Calling Its PDF Section Done

Before I call a PDF section done on any WordPress site, I do not only check if the files are uploaded.

I check if people can actually find them.

A PDF section may look fine from the outside. But behind the scenes, some files may not be searchable. Scanned PDFs may not work. Private files may show in public search. Large PDFs may fail before they finish processing.

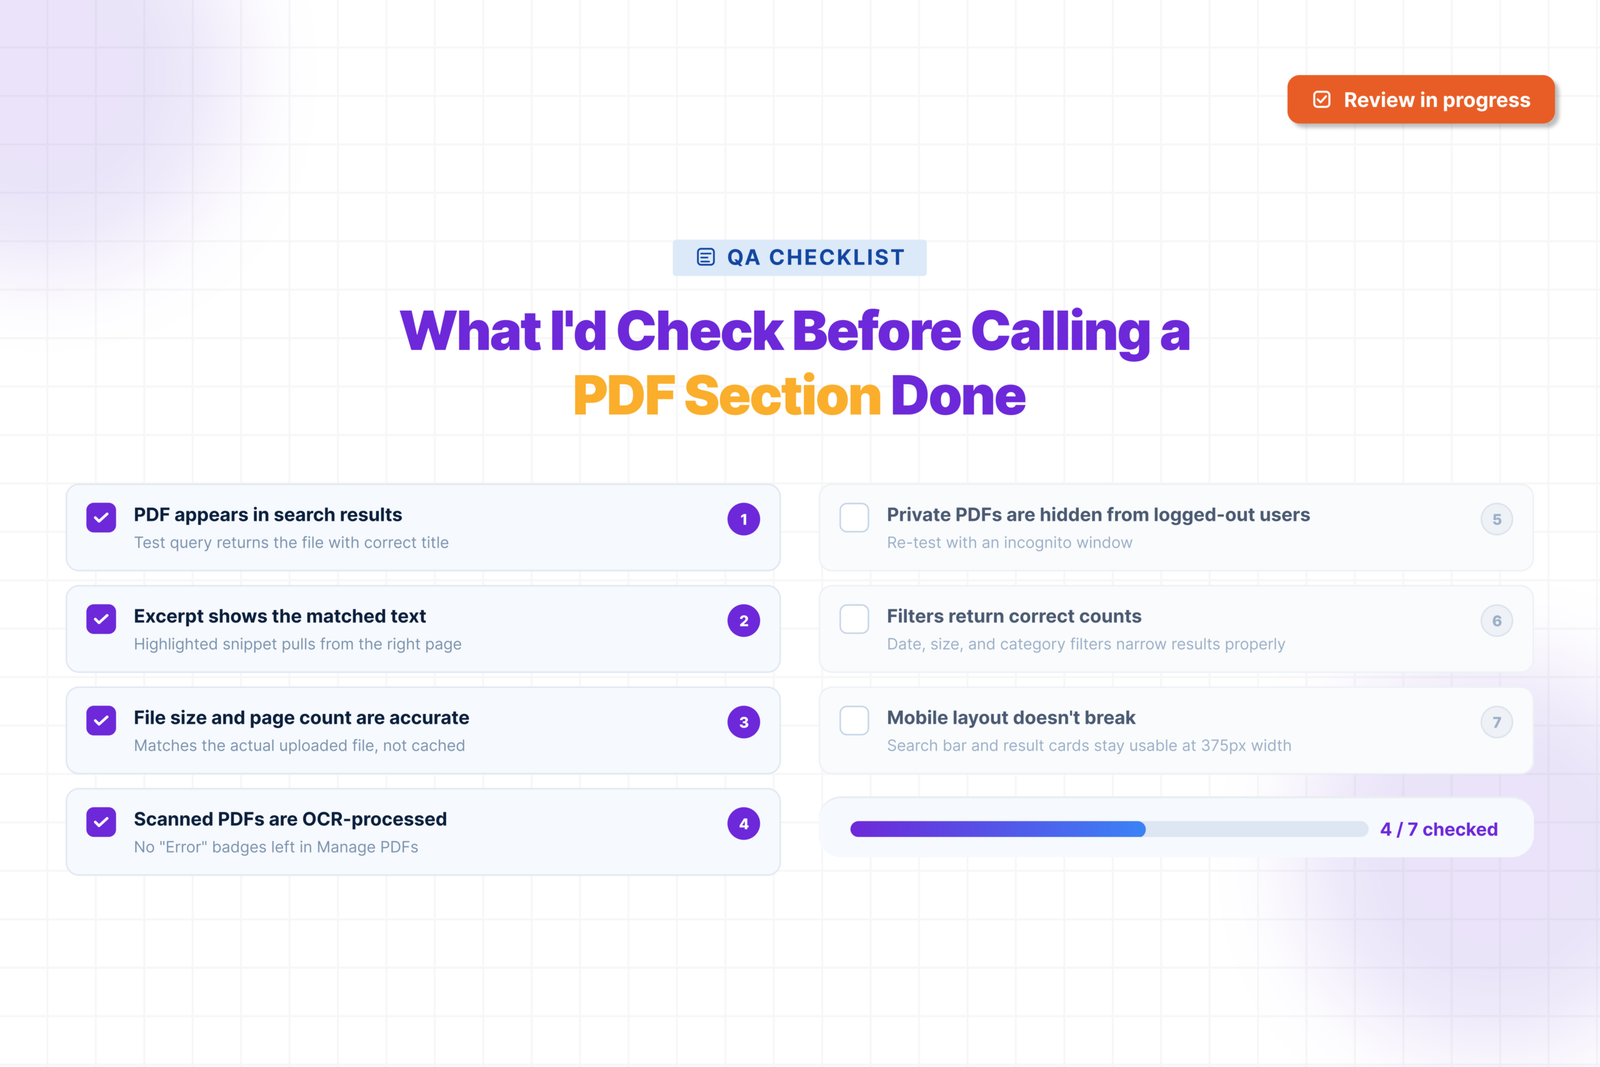
Here are the 7 checks I would run before saying a WordPress PDF section is ready.

Check 1 β€” Is every PDF actually indexed?

The first thing I check is whether each PDF is indexed.

When you upload a PDF to WordPress, WordPress stores the file. But it does not read the text inside the PDF by default. So a visitor may search for a word that exists inside the PDF and still get no result.

In WebEquipe PDF Search, I would go to the Media Library and check the PDF status column. This shows which files are indexed and which files still need work.

After installing the plugin, I would run Re-index All PDFs. This helps the plugin check the PDFs that were already uploaded before the plugin was installed.

If a file still shows Not Indexed after that, I would not ignore it. It may be too large. It may be scanned. It may have failed while processing. Or it may simply need to be indexed again.

For a small site, I would check every PDF. For a large site, I would filter by status and start with the problem files.

Check 2 β€” Are there scanned PDFs in the library?

This is a common reason PDF search does not work.

Some PDFs are text-based. These are usually made from Word, Google Docs, or another document tool. You can open the PDF, select a word, copy text, and search inside it.

Scanned PDFs are different. They are images of pages. Someone scanned a paper document and saved it as a PDF. It looks like a normal PDF, but there is no real text inside for the plugin to read.

The quick test is simple. Open the PDF in a browser and try to highlight a word.

If you can select the word, it is text-based. If your mouse only draws a box over the page, it is probably scanned.

Normal PDF indexing cannot read scanned text. The plugin tries to extract text, but there is nothing to extract. That is why scanned PDFs may show an error or stay missing from search.

If scanned PDFs need to be searchable, they need OCR. OCR reads the image and turns the words into searchable text.

Check 3 β€” Are private documents showing up in public search?

The next thing I check is visibility.

A lot of teams assume that if a PDF is not linked clearly, it is private. That is not true. If a PDF is uploaded to WordPress and indexed, it may appear in search results unless visibility is controlled properly.

There are two different needs here.

If a PDF should not appear in search at all, use Exclude. This removes the file from search indexing. The PDF stays in the Media Library, but it does not show in search results.

If a PDF should be searchable only for logged-in users, use Private PDF Search. This is useful for member handbooks, staff documents, or client resources.

I always test this from both sides. First, I search while logged in. Then I open a private/incognito window and search again as a logged-out visitor. If a restricted document appears publicly, the PDF section is not ready.

PDF search is not only about helping users find documents. It is also about making sure the wrong users cannot find the wrong documents.

Check 4 β€” Does the search form work standalone?

I also test the PDF search form separately from the main website search.

For many websites, this matters a lot. A resource center, document portal, help section, or membership area may need its own PDF-only search form. Visitors in that section usually do not want blog posts, pages, or products mixed into the results. They only want documents.

With WebEquipe PDF Search, the shortcode form can be added to a page using:

[ webequipe_pdf_search_form]

I would place this on a test page and search for a few known PDF terms. I check whether the right results appear, whether the title makes sense, whether the excerpt is useful, and whether the file link opens correctly.

This is also helpful when the main WordPress search is controlled by another plugin or theme. A standalone form keeps PDF search easier to test and manage.

Check 5 β€” What do zero-result searches look like?

A search system should also be tested when it fails.

I always try a few searches that should return no results. Visitors may use the wrong word, a short term, a spelling mistake, or a phrase that is not inside any PDF.

If the page only says β€œNo results found” with no next step, users may think the site is broken. They may not know whether the document is missing, not indexed, private, or named differently.

A better zero-result message should help them continue. It can suggest trying another keyword, checking spelling, browsing the document category, or contacting the site owner.

This is a small detail, but it matters in real use. A good empty result page can stop visitors from giving up too quickly.

Check 6 β€” Is the excerpt length right?

PDF search results need context.

If the result only shows the file name, users may not know whether that PDF is useful. A good excerpt shows the matching text and helps the visitor decide whether to open the file.

The default excerpt length is around 200 characters. That may be fine for short documents, but technical PDFs, manuals, reports, and policies often need more context.

I would search for a term inside a PDF and check the front-end result. Does the excerpt show enough surrounding text? Does it explain why the PDF matched? Or is it too short to be helpful?

If needed, I would adjust the excerpt length from the PDF search display/settings area. This is not only a design decision. It affects whether users trust the result.

Check 7 β€” Are large PDFs processing correctly?

Large PDFs need extra attention.

A small PDF may index quickly. A large PDF with many pages can take longer. If the server has a low timeout limit, indexing may stop before it finishes.

That is why I check whether Background Processing is enabled for large libraries or large files.

Background Processing lets the plugin handle indexing in a queue instead of trying to complete everything in one browser request. This is safer for websites with many PDFs or heavy documents.

If it is turned off, large PDFs may stay stuck in Processing, fail during indexing, or never become searchable. The admin may think everything is done, but some important files are still missing.

I would also check the index activity or processing log. If I see repeated failures, timeout errors, or files stuck for too long, I would fix that before approval.

Conclusion

Before calling a WordPress PDF section done, I would check more than the upload page.

I would confirm that PDFs are indexed, scanned files are handled, private files are protected, the standalone search form works, zero-result searches are helpful, excerpts give enough context, and large PDFs process correctly.

For text-based PDFs, the free WebEquipe PDF Search plugin is enough to get started. If the site has scanned documents or member-only PDFs, those need extra handling. But the first step is always the same: check the library properly before calling the work complete.
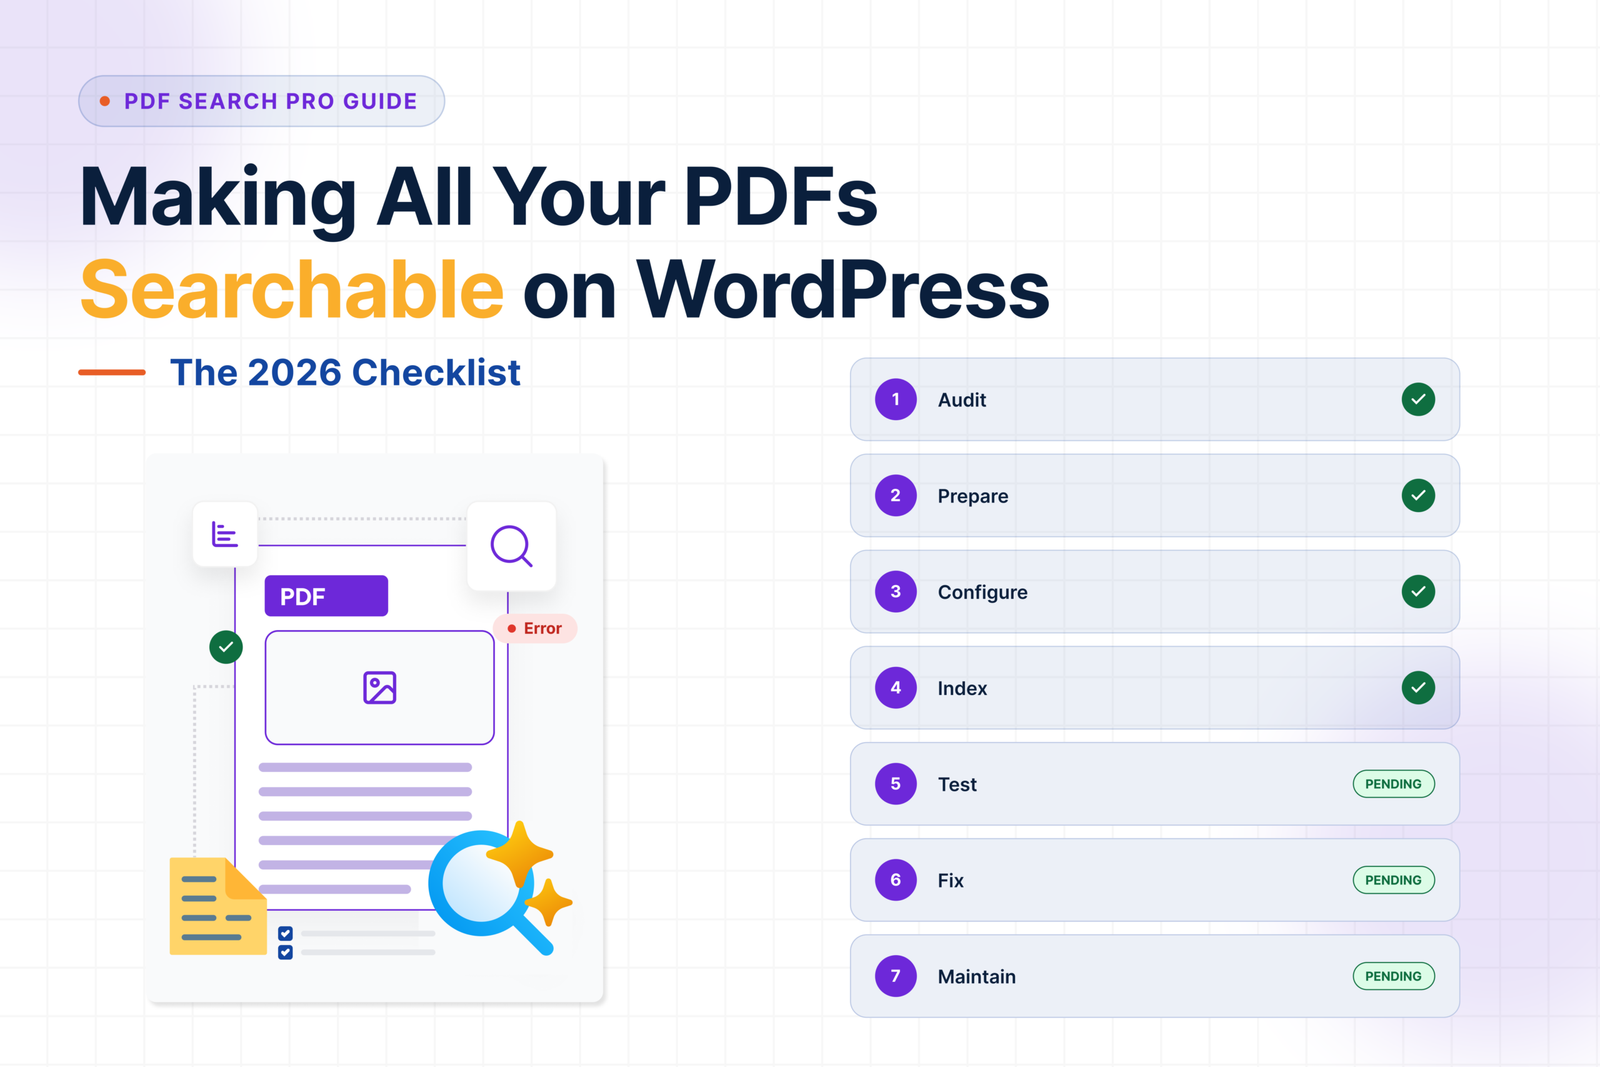
Checklist: Making All Your PDFs Searchable on WordPress in 2026

Checklist: Making All Your PDFs Searchable on WordPress in 2026

Getting PDF search working on WordPress isn’t complicated β€” but it’s easy to miss a step and end up with half your library invisible to search, a handful of Error files nobody’s looked at, or private documents showing up where they shouldn’t.

This checklist covers the full process from start to finish. Use it when setting up PDF search for the first time, after a major plugin update, or as a periodic audit on a large document library.

Table of Contents

  1. Audit Your PDF Library
  2. Prepare Your PDFs
  3. Install and Configure the Plugin
  4. Index Your Library
  5. Test Search
  6. Handle Problem Files
  7. Ongoing Maintenance

Step 1 β€” Audit Your PDF Library

Before touching any plugin settings, know what you’re working with.

πŸŸ₯ Identify how many PDFs you have.

Go to Media β†’ Library, filter by PDF file type, and get a rough count. Large libraries β€” hundreds of files β€” will take longer to index and may need Background Processing enabled from the start.

πŸŸ₯ Separate text-based PDFs from scanned ones.

Open a sample of your PDFs in a browser and try to highlight text. If you can select words, it’s text-based. If you can’t, it’s scanned. Scanned PDFs need OCR β€” a paid feature β€” so knowing how many you have tells you whether you need a Pro plan from day one or whether the free plugin covers your whole library.

πŸŸ₯ Flag PDFs that shouldn’t be searchable.

Drafts, outdated versions, internal working documents, anything that shouldn’t appear in public search results β€” note these now. You’ll exclude them during setup.

πŸŸ₯ Flag PDFs that should be restricted to logged-in users.

Member handbooks, staff policies, client resources β€” anything that should be searchable but only by people who are signed in. These get set to Private. Also a paid feature.

Step 2 β€” Prepare Your PDFs

A few things to sort out before indexing saves problems later.

πŸŸ₯ Clean up filenames.

The filename becomes the title in search results. 2025-annual-report.pdf is useful. doc-FINAL-v3-revised.pdf is not. Rename files with messy names before indexing β€” renaming after means re-indexing.

πŸŸ₯ Remove password protection from files that need to be searchable.

Password-protected PDFs can’t be indexed by any method. If a file needs to be searchable, the password needs to come off first.

πŸŸ₯ Check file sizes.

The default maximum indexable file size is 50MB. Files above that won’t be processed unless you raise the limit in settings. Check if any of your PDFs exceed this and decide whether to raise the limit or split those files.

πŸŸ₯ Make sure PDFs are in your WordPress Media Library.

The plugin indexes PDFs attached to WordPress. Files hosted externally or embedded via iframe won’t be picked up.

Step 3 β€” Install and Configure the Plugin

πŸŸ₯ Install WebEquipe PDF Search.

Go to Plugins β†’ Add New, search for WebEquipe PDF Search, install and activate. For scanned PDFs or private search, activate your Pro or Agency licence in PDF Search β†’ Settings.

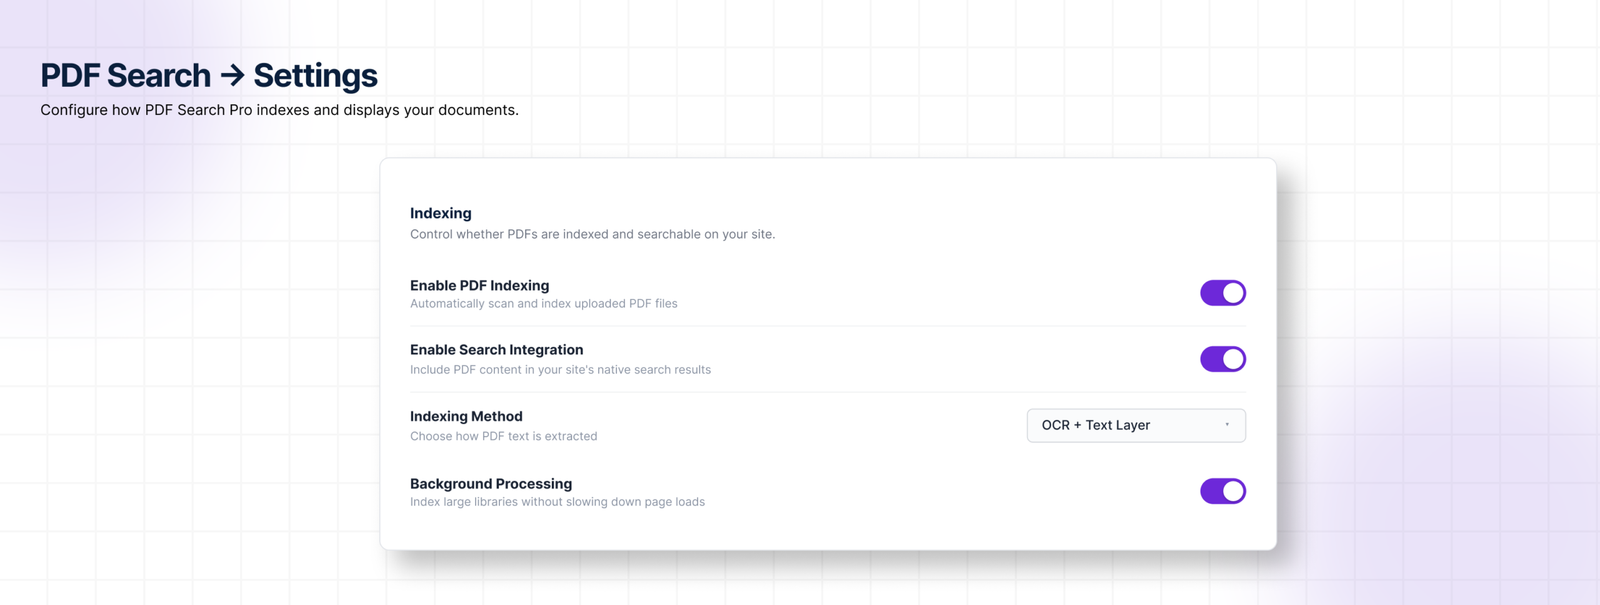
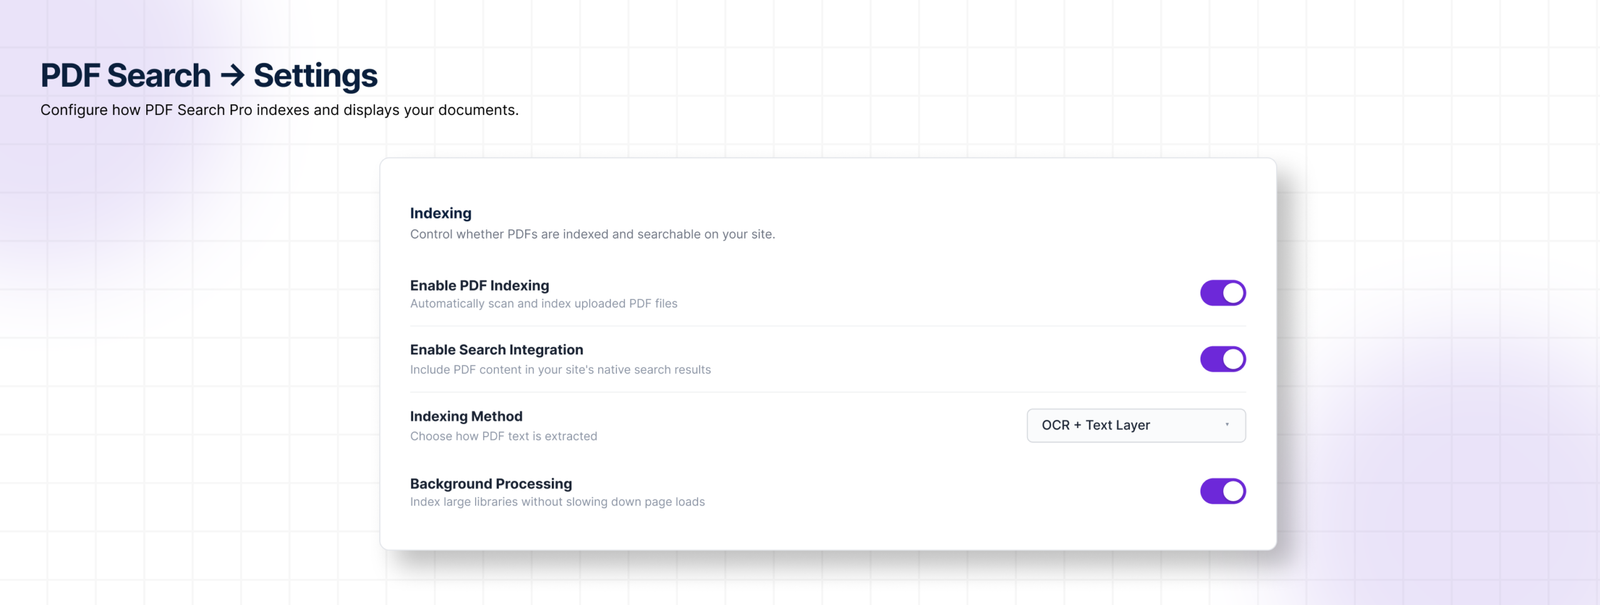
πŸŸ₯ Turn on Enable PDF Indexing.

In PDF Search β†’ Settings β€” this ensures new uploads get indexed automatically going forward.

πŸŸ₯ Turn on Enable Search Integration.

Also in PDF Search β†’ Settings β€” this makes PDF results appear in your site’s standard WordPress search. Leave it off if you only want PDFs in a dedicated shortcode form.

πŸŸ₯ Set your Indexing Method.

  • Text-based PDFs only β†’ Native
  • Scanned PDFs only β†’ OCR Only
  • Mix of both β†’ Native + OCR Fallback (recommended for most sites)

πŸŸ₯ Enable Background Processing for large libraries.

In PDF Search β†’ Settings β†’ Advanced. Essential for sites with large PDFs or many files β€” moves indexing into a background queue so it doesn’t hit PHP execution limits.

πŸŸ₯ Set Default Search Visibility if needed.

If most new uploads should be Private by default, set this in PDF Search β†’ Settings. Individual files can still be switched to Public as needed.

πŸŸ₯ Set your file size limit.

If you have PDFs over 50MB that need indexing, raise the Maximum File Size in PDF Search β†’ Settings.

Set your file size limit

Step 4 β€” Index Your Library

πŸŸ₯ Run Re-index All PDFs.

Go to PDF Search β†’ Dashboard and click Re-index All PDFs. This processes every non-excluded PDF in your library. For large libraries this runs in batches β€” leave it running and check back.

πŸŸ₯ Exclude PDFs that shouldn’t be searchable.

While indexing is running or after it completes, go through PDF Search β†’ Manage PDFs and Exclude any files you flagged in Step 1. Excluded files get skipped in all future re-index runs.

πŸŸ₯ Set Private PDFs.

For files that should be searchable only by logged-in users, open each one in Media β†’ Library, set Search Visibility to Private, and save. Or use the bulk action Make Private in Manage PDFs for multiple files at once.

πŸŸ₯ Check index coverage.

Once Re-index All PDFs completes, go to PDF Search β†’ Dashboard and check the coverage percentage. If it’s significantly below 100%, there are PDFs that need attention.

πŸŸ₯ Test standard search.

Search for a specific phrase you know appears inside one of your PDFs. It should appear in results with a title, excerpt from the matching page, and file details.

πŸŸ₯ Test a PDF-only shortcode form if you’re using one.

Add [ webequipe_pdf_search_form ] to a test page and search for the same phrase. Confirm results appear correctly.

πŸŸ₯ Test private PDF visibility.

Open a private browsing window and search for a PDF you’ve set to Private. It should not appear. Log in and search again β€” it should show up.

πŸŸ₯ Test an excluded PDF.

Search for content from a PDF you’ve excluded. It should not appear in any results.

Test an excluded PDF.

Step 6 β€” Handle Problem Files

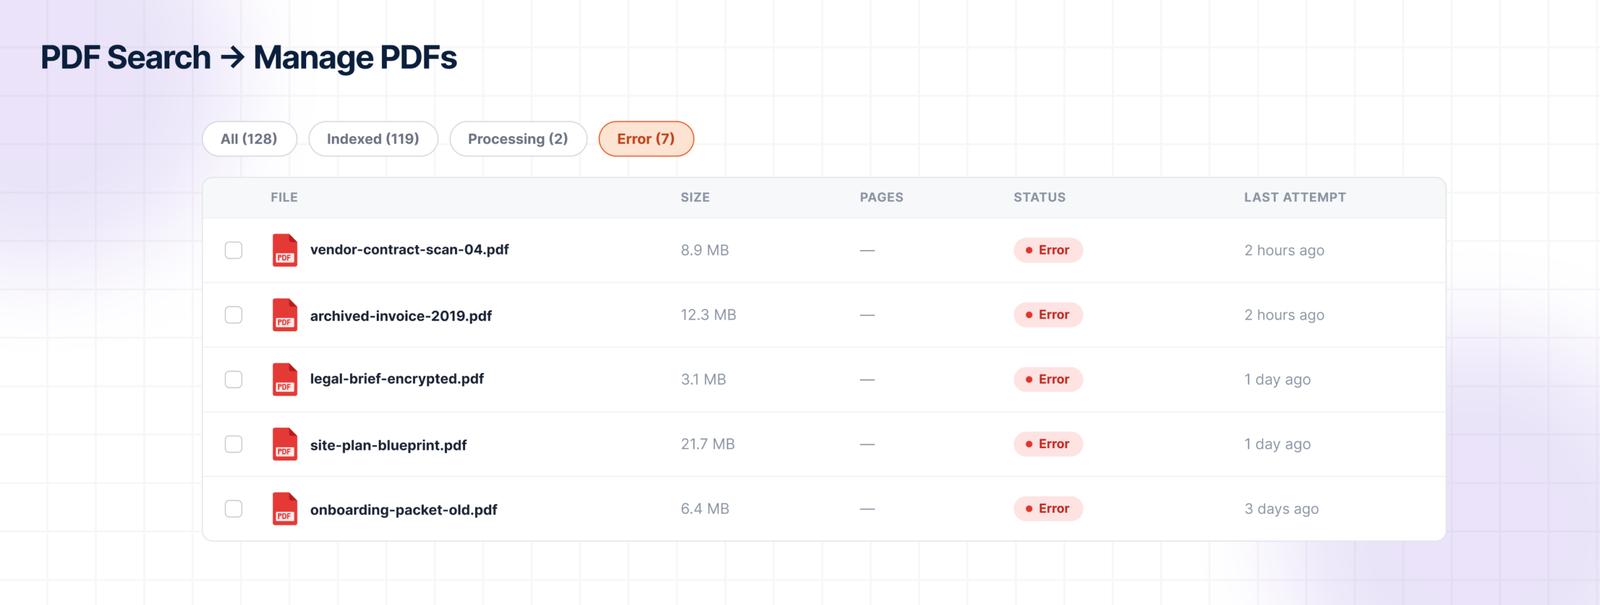
πŸŸ₯ Check for Error status PDFs.

Go to PDF Search β†’ Manage PDFs and filter by Error. These are files that failed indexing.

  • If they’re scanned β†’ run bulk action Index OCR (requires paid plan)
  • If they’re password-protected β†’ remove the password, then re-index
  • If they’re corrupted β†’ replace the file, then re-index

πŸŸ₯ Check for PDFs stuck in Processing.

If any files have been in Processing status for an unusually long time, check the cron status indicator on the Dashboard. A broken cron is the most common cause of stalled indexing jobs.

πŸŸ₯ Review the Index Activity log.

Go to PDF Search β†’ Index Activity and scan for Failed runs. Click the detail icon on any failed entry to see exactly what went wrong. This is the fastest way to diagnose stubborn files.

Review the Index Activity log.

Step 7 β€” Ongoing Maintenance

PDF search isn’t set and forget. A few habits keep it running cleanly.

πŸŸ₯ Re-index after replacing a PDF.

If you swap out a file for a newer version, the index doesn’t update automatically. Go to that PDF in your Media Library and click Re-index.

πŸŸ₯ Check index coverage periodically.

New PDFs uploaded without indexing enabled, files that failed silently, PDFs that got excluded by mistake β€” these all show up as gaps in coverage. A monthly check of the Dashboard coverage metric catches them early.

πŸŸ₯ Monitor OCR credit usage.

If you’re on a paid plan using OCR, keep an eye on your monthly page allowance in PDF Search β†’ Dashboard. Running out mid-month means new scanned uploads queue but don’t process until credits reset.

πŸŸ₯ Export Index Activity logs for large libraries.

For sites managing hundreds of PDFs, exporting the Index Activity CSV periodically gives you a record of what was indexed, when, and by which method. Useful for audits and for diagnosing patterns in failures.

πŸŸ₯ Test search after WordPress or plugin updates.

Major WordPress updates and plugin updates can occasionally affect how search results are rendered. A quick search test after any significant update confirms everything is still working.

Quick Reference β€” Status Badges in Manage PDFs

Status What it means Action
Indexed In search, working correctly None needed
Not Indexed In library, not yet processed Click Index
Processing Currently being indexed Wait
Scheduled Queued for background processing Wait
Error Indexing failed Check error detail, re-index or use OCR
Excluded Removed from search deliberately Click Include to restore

Frequently Asked Questions

How long does Re-index All PDFs take?

Depends on library size and file sizes. A library of 50 standard PDFs typically completes in a few minutes. Several hundred PDFs, or files with many pages, can take longer β€” especially if Background Processing is handling them in batches. Check progress in PDF Search β†’ Index Activity.

Do I need to re-index every time I upload a new PDF?

No. With Enable PDF Indexing turned on, new uploads are indexed automatically. You only need to run Re-index All PDFs manually for files that were uploaded before the plugin was installed, or to reprocess files after changing the indexing method.

What’s the difference between Exclude and Delete?

Exclude only affects search indexing β€” the file stays in your Media Library and is still accessible via its direct URL. Delete removes the file entirely from WordPress. Use Exclude for files you want to keep but not make searchable.

Can I index PDFs that are stored outside WordPress?

No. The plugin indexes PDFs in your WordPress Media Library. Files hosted on external servers, embedded via iframe, or linked from third-party storage aren’t picked up.

What happens to my index if I deactivate the plugin?

The index tables stay in your database β€” nothing is deleted on deactivation. If you want a full clean removal, enable Delete Data on Uninstall in PDF Search β†’ Settings β†’ Advanced before uninstalling.

Done

If you’ve worked through every step above, your PDF library is fully indexed, problem files are diagnosed, restricted documents are properly controlled, and you have a maintenance routine in place.

For the full setup guide if you’re starting from scratch:

How to Make WordPress Search Inside PDF Files β†’

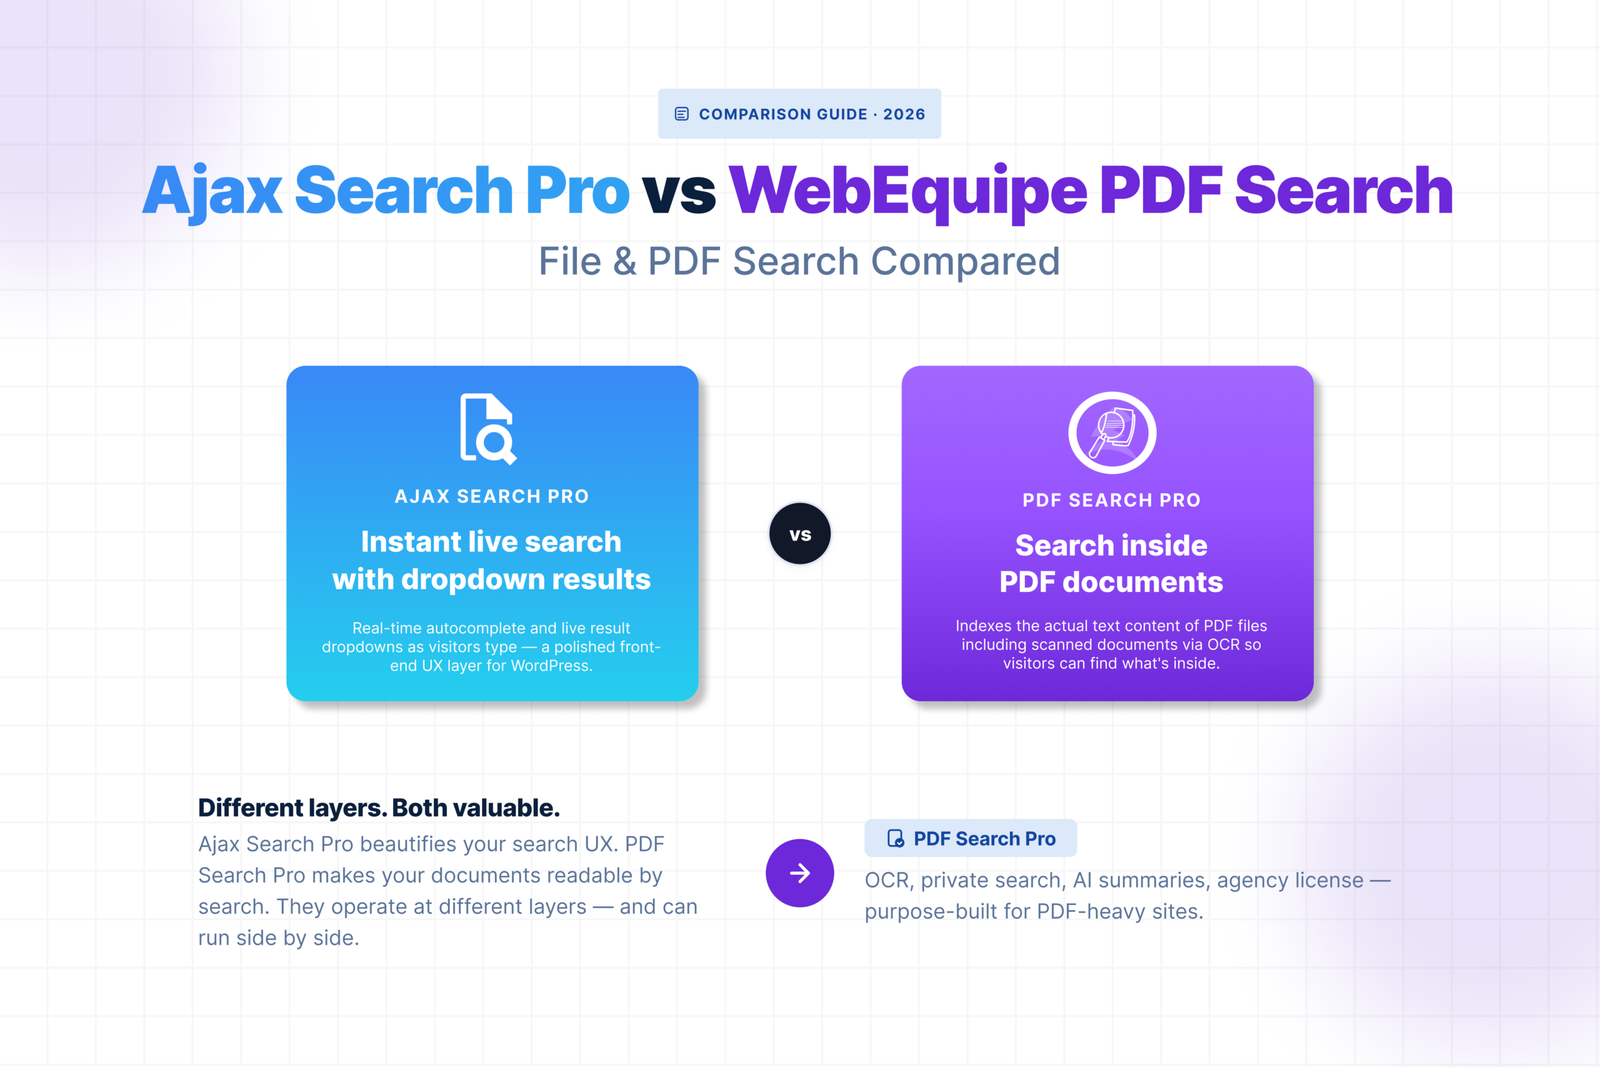
Ajax Search Pro vs WebEquipe PDF Search: File & PDF Search Compared

Ajax Search Pro vs WebEquipe PDF Search: File & PDF Search Compared

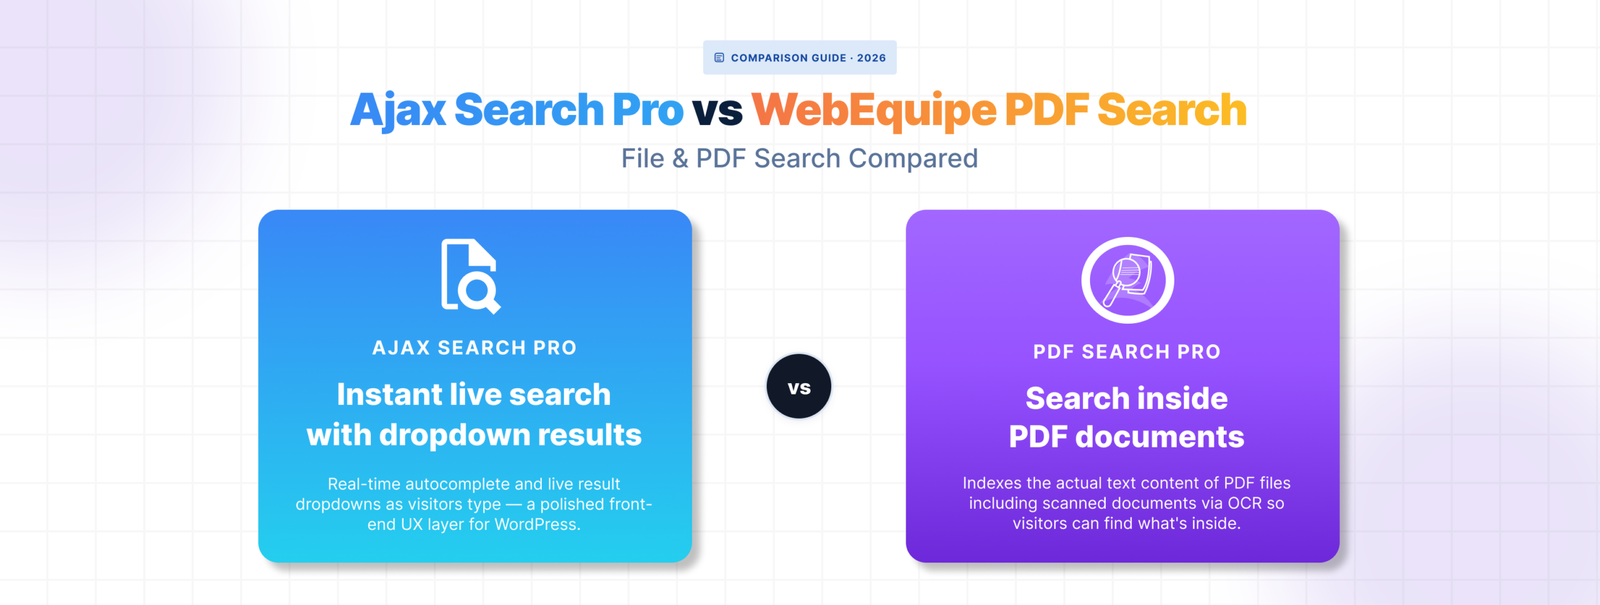
Ajax Search Pro is a popular choice for live search on WordPress β€” the kind where results appear as you type, with images, custom post types, and styled dropdowns. For front-end search UX it’s capable and well-supported.

But if your visitors need to find content inside PDF files β€” not just PDF titles, but the actual text on page four of a document β€” Ajax Search Pro wasn’t built for that. File content search is a limited feature, not a core one.

Here’s where the difference shows up.

What Ajax Search Pro Does Well

Ajax Search Pro delivers real-time search with a polished front-end experience. Results appear as the user types, with support for featured images, custom post types, WooCommerce products, and custom fields. The visual customisation is extensive β€” dropdown styles, result layouts, colour schemes, mobile behaviour.

For sites where the search experience itself is a priority β€” e-commerce, directories, content-heavy blogs β€” that live search UX is genuinely valuable.

How Ajax Search Pro Handles File Content and PDFs

Ajax Search Pro can index file attachments including PDFs, but what it indexes is limited. It reads the text layer of standard PDFs using server-side extraction, which works for straightforward text-based documents.

The file content search feature isn’t the plugin’s primary focus though. Configuration is more involved than a dedicated document search plugin, there’s no dedicated PDF management screen, and diagnosing why a specific PDF isn’t appearing in results means working through general plugin settings rather than a per-file workflow.

Scanned PDFs aren’t supported. There’s no OCR built in. And there’s no native way to mark individual PDFs as visible only to logged-in users.

Where It Falls Short for Document-Heavy Sites

πŸŸ₯ No OCR for scanned documents

Scanned PDFs have no extractable text layer. Ajax Search Pro can’t index them. For sites with archives of older documents, historical records, or any content that was scanned rather than digitally created, those files are simply invisible to search.

πŸŸ₯ No private PDF search

Ajax Search Pro doesn’t have a built-in mechanism for restricting individual PDFs to logged-in users. If you need member resources or restricted documents to be searchable only by signed-in visitors, you’d need to handle that through a separate plugin.

πŸŸ₯ No dedicated PDF management workflow

There’s no screen in Ajax Search Pro that shows you which PDFs are indexed, which have failed, and why. If a document isn’t showing up in search, there’s no per-file status to check. Troubleshooting means working backwards through configuration rather than looking at a clear status log.

πŸŸ₯ Live search focus can add unnecessary complexity

If you’re running a document library or resource centre, you probably don’t need live as-you-type search with styled dropdowns and image previews. Ajax Search Pro’s strength is also its overhead β€” you’re configuring a lot of front-end behaviour to get to the document indexing feature underneath.

How WebEquipe PDF Search Compares

WebEquipe PDF Search does one thing β€” makes PDF content searchable in WordPress. No live search dropdowns, no e-commerce integration, no directory features. Just a clean pipeline from PDF upload to indexed, searchable content.

The free version handles text-based PDFs with auto-indexing on upload, WordPress search integration, a shortcode form, and per-file status management. The Pro version adds OCR for scanned documents and Private PDF Search for logged-in-only visibility.

For a document library, resource centre, or any site where PDFs are the primary content, it’s a simpler and more focused setup.

Feature Comparison

Feature WebEquipe PDF Search Ajax Search Pro
Text-based PDF indexing βœ“ Paid βœ“ Paid ($99/yr)
Scanned PDF / OCR βœ“ Paid (from $89/yr) Γ—
Private / restricted PDFs βœ“ Paid Γ—
Per-file status management βœ“ Γ—
Index Activity log βœ“ Γ—
Free tier with PDF search βœ“ Γ—
Live as-you-type search Γ— βœ“
Styled search dropdown Γ— βœ“
WooCommerce search Γ— βœ“
Starting price (paid) $89/yr ~$36 one-time

Can You Use Both Together

Yes β€” and for some sites this makes sense.

Ajax Search Pro handles the live search experience across posts, pages, and products. WebEquipe PDF Search handles the document indexing workflow β€” OCR, private search, per-file status management β€” through its own dedicated shortcode form.

To avoid both plugins trying to modify the same WordPress search results, leave Enable Search Integration off in WebEquipe PDF Search settings. Use the [webequipe_pdf_search_form] shortcode on your documents or resources page for PDF-specific search, and let Ajax Search Pro handle live search everywhere else.

Who Should Use Which

πŸŸ₯ Use WebEquipe PDF Search if:

  • PDF content search is your primary need
  • You have scanned documents that need OCR
  • You need to restrict certain PDFs to logged-in users only
  • You want a dedicated document management workflow with per-file status

πŸŸ₯ Use Ajax Search Pro if:

  • You need live as-you-type search with a polished front-end experience
  • Your site is e-commerce, a directory, or content-heavy with lots of post types
  • PDF search is a minor secondary need alongside broader search features

πŸŸ₯ Use both if:

  • You want Ajax Search Pro’s live search UX for your site and WebEquipe’s PDF-specific workflow for your document library

Frequently Asked Questions

Does Ajax Search Pro search inside PDF files?

It can extract and index text from standard text-based PDFs. Scanned PDFs aren’t supported β€” there’s no OCR built in. For straightforward text-based documents on a site that’s already using Ajax Search Pro, it works for basic cases. For document-heavy sites with scanned files or private search requirements, it falls short.

Is WebEquipe PDF Search cheaper than Ajax Search Pro?

For text-based PDF search, WebEquipe is free. Ajax Search Pro is a one-time purchase of around $36 but doesn’t have a free tier with PDF content search. For scanned PDFs, WebEquipe Pro starts at $89/yr.

Can I use Ajax Search Pro for live search and WebEquipe for PDF content search?

Yes β€” this is a clean setup. Disable Enable Search Integration in WebEquipe settings and use the shortcode form for PDF search. Ajax Search Pro handles live search everywhere else.

Does Ajax Search Pro support private PDF search for logged-in users?

Not natively. Restricting PDF visibility to logged-in users requires a separate plugin. WebEquipe PDF Search Pro has Private PDF Search built in.

For the full WebEquipe PDF Search setup:

How to Make WordPress Search Inside PDF Files β†’