๐ŸŽ‰ Save 10% Extra on the Webequipe PDF Search Plugin Annual Plan โ€” Use code YEARLY10 ยท Limited-time offer ยท Get discount โ†’

The Contract Was in the PDF. The Client Never Found It.

the-contract-was-in-the-pdf-the-client-never-found-it

A small estate-planning firm we’ll call Harlow & Vance had done the content marketing work most firms skip. Plain-language guides on probate, power of attorney, living trusts, each one a genuinely useful PDF, written to help prospective clients understand what they were walking into before ever booking a consultation.

Dozens of these guides sat in the WordPress Media Library. Each one had taken real time to write. None of them ever showed up when someone searched the site.

Where the Client Actually Was

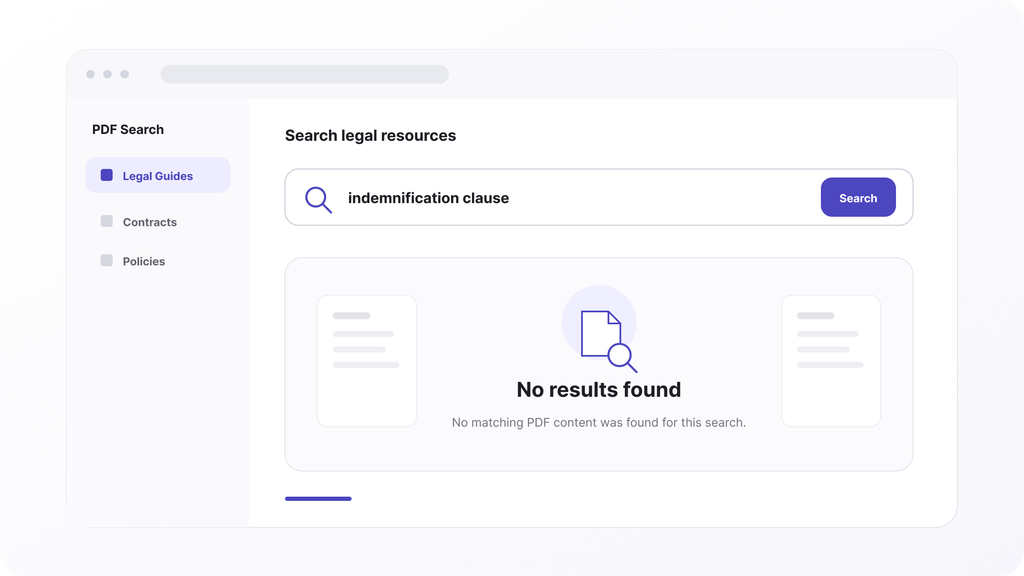
A prospective client, someone worried about a parent’s power of attorney, would land on the site and search “power of attorney checklist.” Nothing came back. Not because the firm hadn’t written that guide, they had, it was sitting right there as a PDF, it’s that WordPress search doesn’t open PDF files by default. It reads what’s typed into posts and pages, and a downloadable guide is neither.

The visitor, finding nothing, would either leave or dig through a resources page manually, scanning file names for anything that looked relevant. Some found what they needed. Many didn’t, and left without ever seeing content the firm had specifically written for them.
search-legal-resources

Why This Mattered More Than It Looked

For a legal or compliance-focused site, this gap is quieter than it is for, say, a product manufacturer. Nobody emails a law firm asking “where’s your PDF on power of attorney,” the way a customer might chase down a manual. They just leave. The cost shows up as a missed lead, not a support ticket, which makes it easy to miss entirely, there’s no complaint to trace it back to.

What Changed

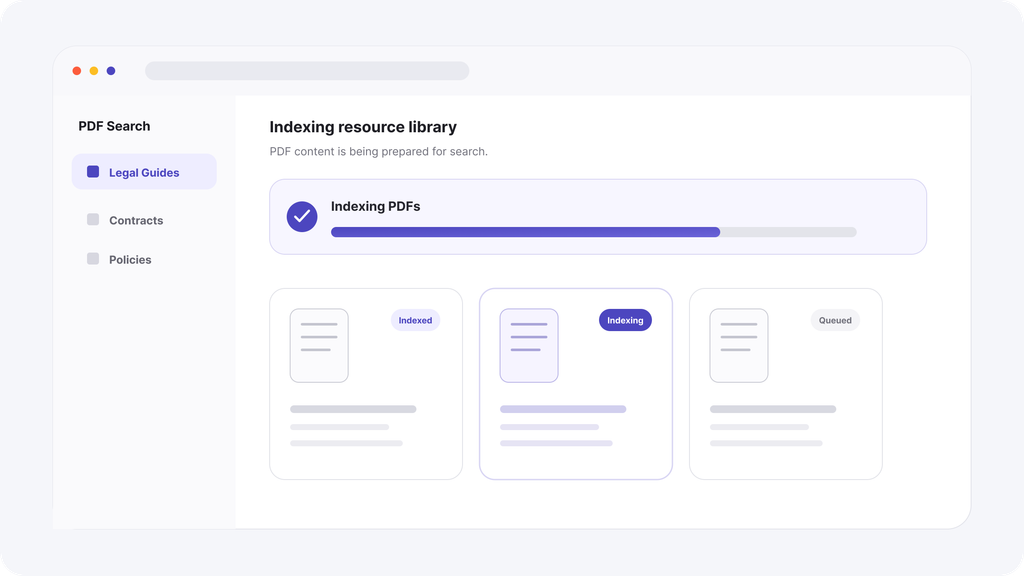
The firm installed WebEquipe PDF Search and indexed the full resource library. Each guide, checklist, and explainer PDF became part of the site’s normal search, the same box visitors already used to find blog posts and practice area pages.
indexing-resources-library

A search for “power of attorney checklist” now returned the exact guide, with an excerpt pulled from the relevant section and the file size shown up front, so a visitor knew what they were opening before clicking.
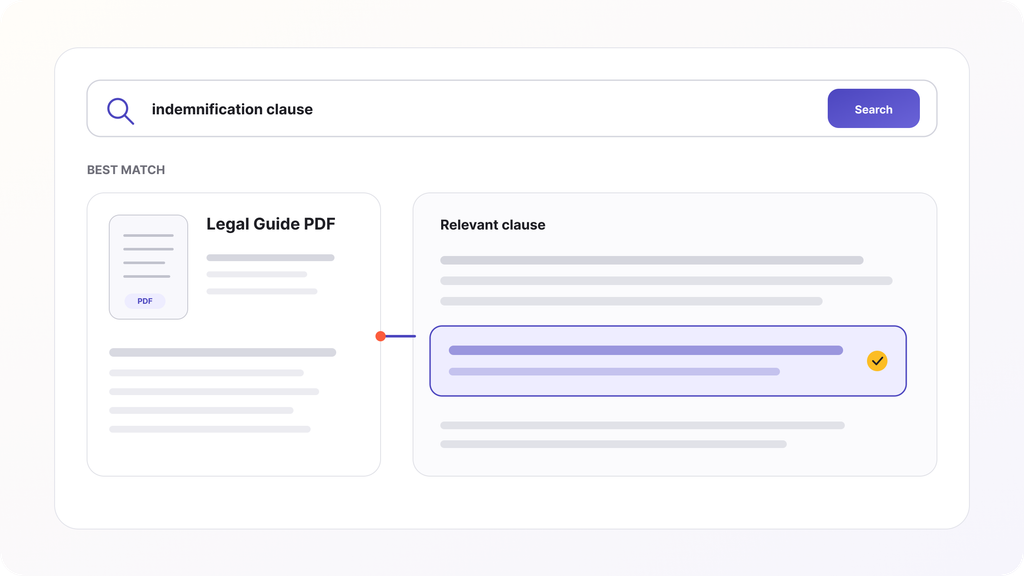
legal-guide-pdf

A Note on Sensitive Content

Worth being direct about something specific to legal and compliance sites: not everything in a resource library belongs in public search. Draft templates, internal compliance checklists, or documents meant only for existing clients should be handled with Exclude, or with Private PDF Search on Pro if the goal is member or client-only visibility rather than removing them from search entirely. The fix for making content findable and the fix for keeping it appropriately restricted are two different settings, and it’s worth deciding deliberately which PDFs belong in which category before running a full re-index.

The Takeaway

If your firm has written genuinely useful client resources and published them as PDFs, the writing isn’t the problem. The problem is that WordPress search was never told those documents exist. That’s a fixable gap, and closing it means the content you already wrote finally does the job it was written for.
View WebEquipe PDF Search plans โ†’

120 Pages, One Answer, Zero Results

120-pages-one-answer-zero-results

Someone lands on a legal aid site looking for one thing: what happens if their landlord hands them an eviction notice with no warning. The site has a tenant rights guide, a genuinely thorough one, 60 pages covering everything from lease basics to court procedure. The answer is in there. It’s just not findable.

They search “eviction notice.” Nothing comes back, because the guide is a PDF and the site’s search has never looked inside a PDF in its life. So they either give up, or they open the document and start scrolling through sixty pages hoping to land near the right section.

This happens constantly on legal and compliance sites, and it’s rarely because the information is missing. It’s because the information is trapped inside a file format search was never built to read.

Why Legal and Compliance PDFs Are Especially Bad at This

Legal documents tend to be long, dense, and precise on purpose. A compliance policy needs to cover every scenario. A client guide needs to be thorough enough to hold up as actual guidance. Nobody writing these documents is trying to bury information, the length is a feature of doing the subject matter justice, not a flaw.

But that thoroughness is exactly what makes them hostile to browse. A 100-plus page policy document with no working search is functionally the same as a locked filing cabinet for anyone who doesn’t already know which page to turn to.

What Full-Text Search Actually Changes

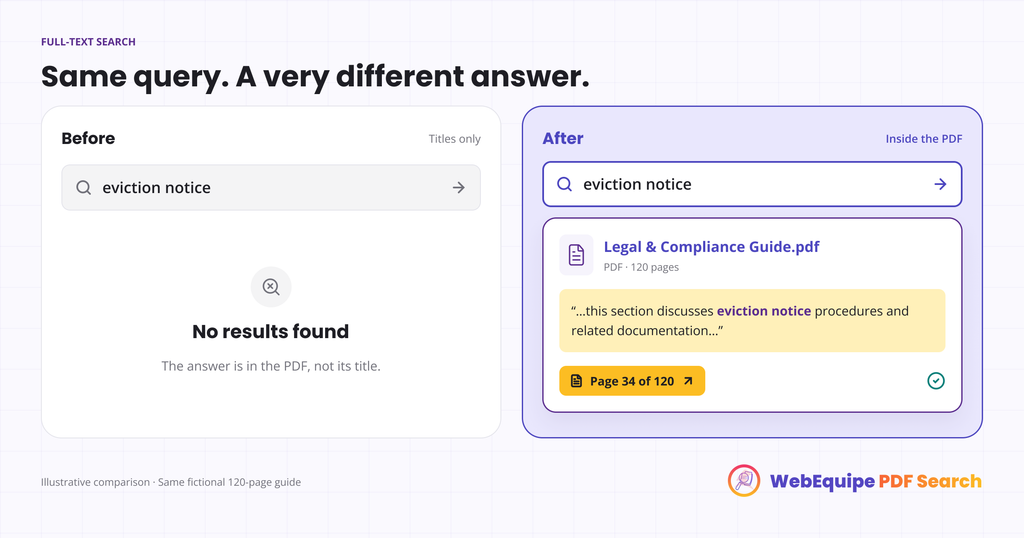
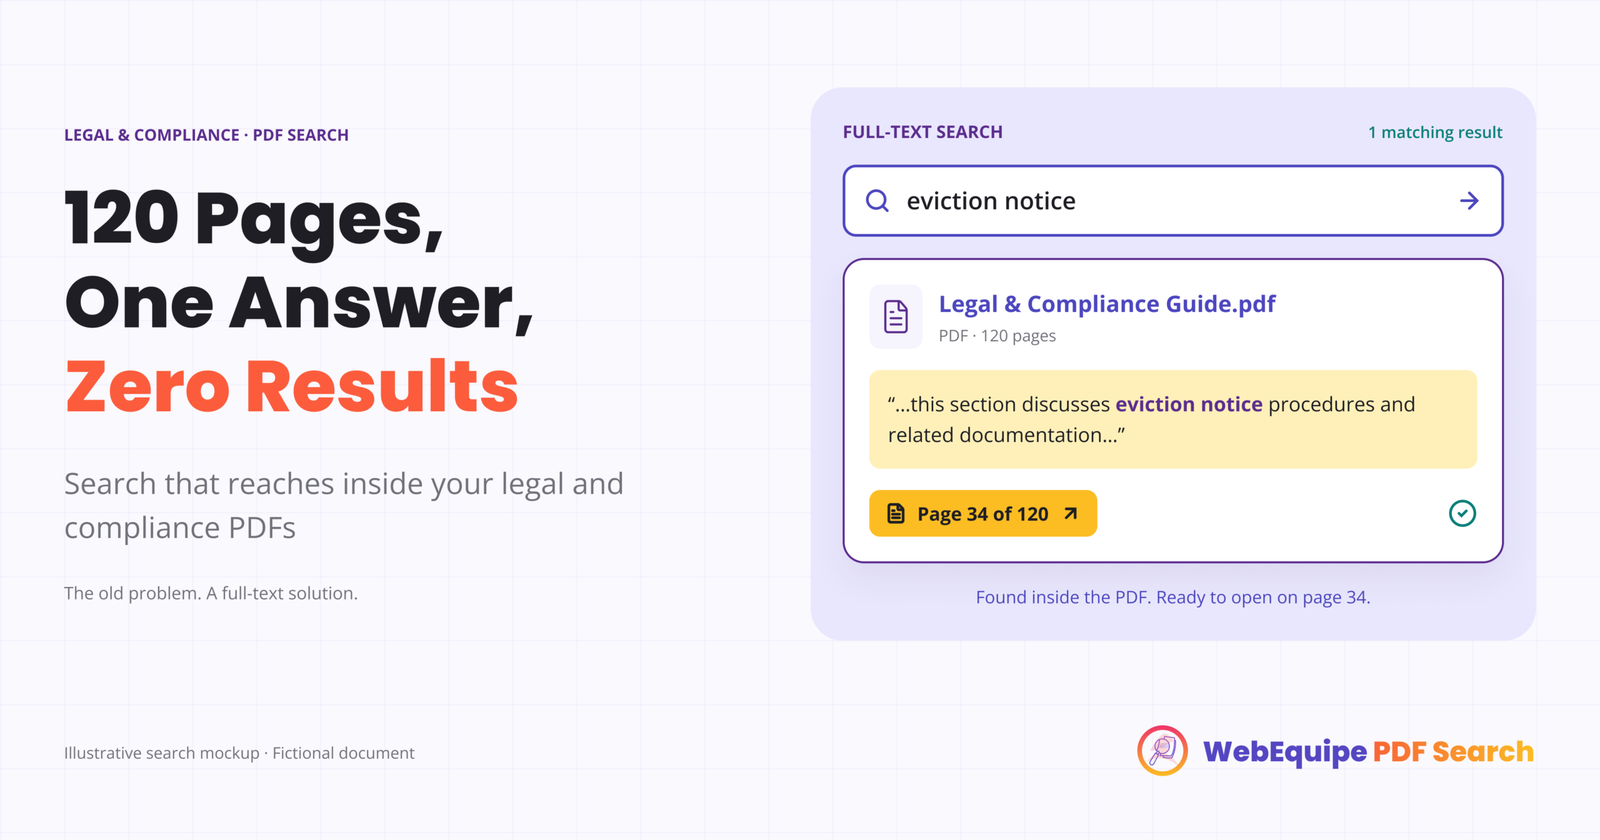
Once PDF Search indexes the tenant rights guide, or the compliance policy, or the case study library, the site’s search stops treating the PDF as a black box. It reads the actual text and adds it to search results, so a search for “eviction notice” returns the guide because the phrase genuinely appears in it, not because someone tagged the file correctly.

This works the same way whether it’s one guide or a whole resource library. A law firm publishing dozens of client handouts, or a compliance team maintaining a stack of policy PDFs, gets the same outcome: search finally reflects what’s actually written, not just what’s in the filename.

same-query-a-very-different-answer

Landing on the Clause, Not the Cover Page

Finding the right document is only step one. A 60-page guide is still 60 pages once someone opens it, and most people won’t scroll through all of it looking for one section.

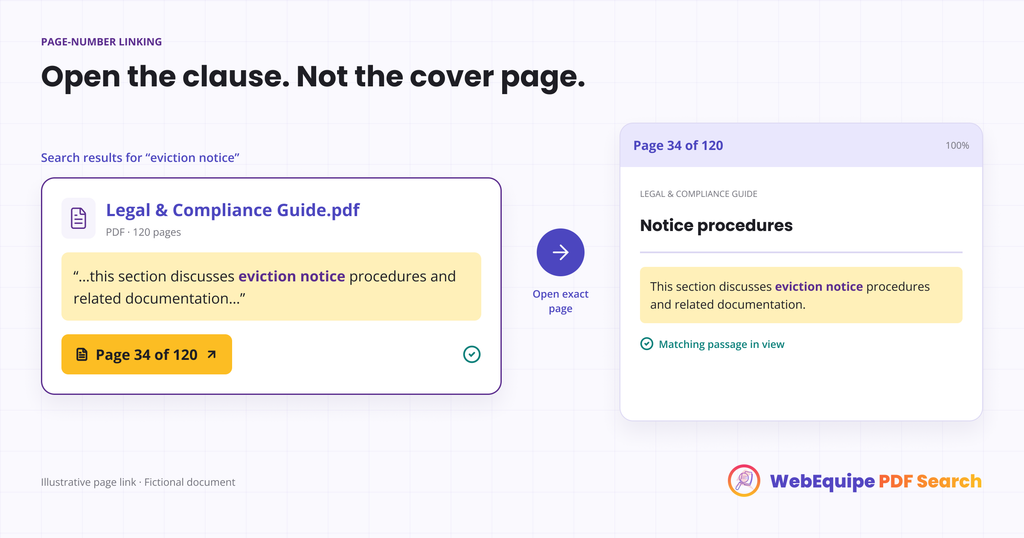
Search results link directly to the page where the match was found. Someone searching “eviction notice” doesn’t land on page one of the guide, they land on the page that actually covers eviction notices. The difference between finding the document and finding the answer disappears.

For legal and compliance content specifically, where the exact wording of a clause often matters, landing on the right page rather than an approximate area of a long document is the whole point.

Older Case Files and Scanned Records

Some legal and compliance archives go back further than digital publishing, older case studies, historical policy versions, records scanned from physical files. Those don’t have real, selectable text, so standard indexing can’t read them.

OCR handles that by converting scanned pages into searchable text during indexing. An older case file becomes just as searchable as something published last week, without anyone retyping it.

open-the-clause-not-the-cover-page

Why This Matters Beyond Convenience

For a legal aid organization, someone who can’t find the answer to “what happens if I get an eviction notice” might not follow up with a call either. They might just assume there’s no help available. For a compliance team, a policy that’s technically published but practically unfindable doesn’t do much for anyone trying to follow it correctly.

Making PDF content searchable isn’t just a UX nicety here. It’s the difference between information existing and information actually reaching the person who needs it.

Frequently Asked Questions

Do we need to restructure our existing guides and policy documents?

No. Indexing works on PDFs exactly as they’re already uploaded.

Will this work for scanned older case files, not just recent digital documents?

Yes, through OCR, which converts scanned pages into searchable text during indexing.

Does search find the exact clause, or just the document it’s in?

Results link to the specific page where the match was found, not just the file.

Can we keep certain documents restricted to logged-in staff or clients only?

Yes. Specific PDFs can be marked private so they stay indexed and searchable for logged-in users while staying out of public search results.

Does this replace how our resource library is currently organized?

No. It adds search on top of whatever structure already exists. Nothing about how documents are displayed needs to change.

How long does OCR take on an older scanned archive?

It depends on volume. Text-based PDFs index immediately at no OCR cost; scanned pages process against your plan’s monthly OCR quota.

Getting Started

Most sites can index an existing library of guides and policies without any restructuring, with older scanned records processed over time as OCR capacity allows.

View PDF Search Pro plans โ†’